Designing Reliable Distributed Tracing Pipelines
Build production distributed tracing with OpenTelemetry: context propagation, sampling strategies, storage backends, log correlation and cardinality.

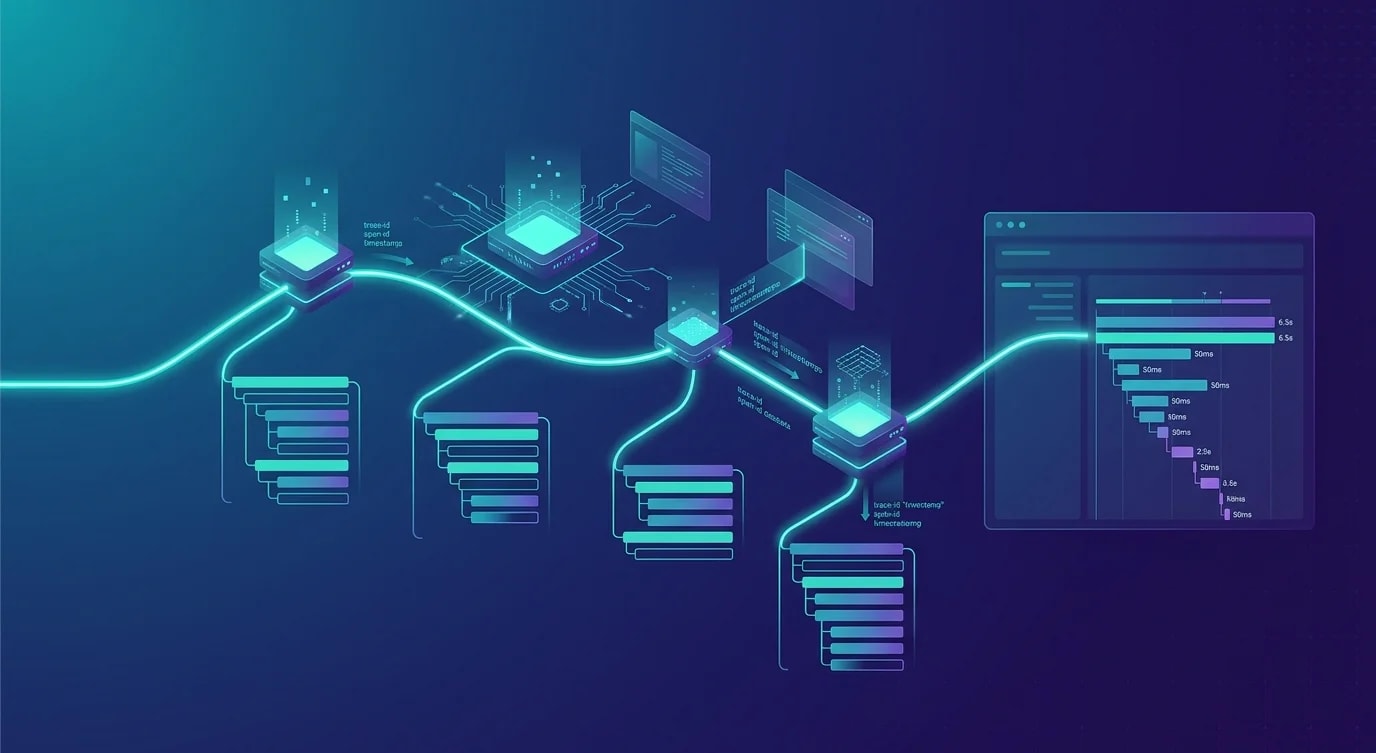
Distributed tracing shows you the complete journey of a request across services. Without it, debugging in a microservices architecture is guesswork—you're staring at individual service logs hoping to correlate timestamps. With it, you see the full request path, where time was spent, and exactly which service caused a failure.
But tracing infrastructure that works in development often breaks in production. The volume of trace data at scale demands intelligent sampling, the storage requirements can dwarf your application databases, and poorly configured context propagation creates gaps that make traces useless at the moment you need them most.
OpenTelemetry Instrumentation
OpenTelemetry provides the vendor-neutral foundation. Instrument once, export to any backend.
// ❌ Manual span creation everywhere — noisy, fragile
import { trace } from "@opentelemetry/api";

async function handleOrder(orderId: string) {
  const span = trace.getTracer("app").startSpan("handleOrder");
  try {
    span.setAttribute("order.id", orderId);
    // 50 lines of manual span management per function
    // Developers forget, spans are inconsistent
  } finally {
    span.end();
  }
}// ✅ SDK setup with automatic instrumentation
import { NodeSDK } from "@opentelemetry/sdk-node";
import {
getNodeAutoInstrumentations,
} from "@opentelemetry/auto-instrumentations-node";
import {
OTLPTraceExporter,
} from "@opentelemetry/exporter-trace-otlp-grpc";
import {
BatchSpanProcessor,
} from "@opentelemetry/sdk-trace-base";
import { Resource } from "@opentelemetry/resources";
import {
ATTR_SERVICE_NAME,
ATTR_SERVICE_VERSION,
} from "@opentelemetry/semantic-conventions";
const exporter = new OTLPTraceExporter({
url: "http://otel-collector:4317",
});
const sdk = new NodeSDK({
resource: new Resource({
[ATTR_SERVICE_NAME]: "order-service",
[ATTR_SERVICE_VERSION]: "2.4.1",
"deployment.environment": process.env.NODE_ENV ?? "development",
}),
spanProcessors: [
new BatchSpanProcessor(exporter, {
maxQueueSize: 2048,
maxExportBatchSize: 512,
scheduledDelayMillis: 5000,
}),
],
instrumentations: [
getNodeAutoInstrumentations({
"@opentelemetry/instrumentation-http": {
ignoreIncomingRequestHook: (req) =>
req.url === "/health" || req.url === "/ready",
},
"@opentelemetry/instrumentation-express": {
enabled: true,
},
"@opentelemetry/instrumentation-pg": {
enhancedDatabaseReporting: true,
},
}),
],
});
sdk.start();
// Graceful shutdown
process.on("SIGTERM", async () => {
await sdk.shutdown();
process.exit(0);
});Auto-instrumentation covers HTTP clients and servers, database drivers, message queues, and gRPC automatically. Manual spans are only needed for business-logic boundaries that auto-instrumentation can't detect.
Sampling Strategies
At production scale, tracing 100% of requests is impractical—the data volume overwhelms storage and the collector pipeline. Sampling decides which traces to keep.
// Head-based sampling: decide at trace start
import {
  ParentBasedSampler,
  TraceIdRatioBasedSampler,
  AlwaysOnSampler,
} from "@opentelemetry/sdk-trace-base";
import { Sampler, SamplingResult } from "@opentelemetry/api";

// Composite sampler: different rates for different traffic
class RuleBasedSampler implements Sampler {
  shouldSample(
    context: any,
    traceId: string,
    spanName: string,
    spanKind: any,
    attributes: Record<string, unknown>
  ): SamplingResult {
    const path = attributes["http.target"] as string;

    // Always trace errors
    const statusCode = attributes["http.status_code"];
    if (statusCode && Number(statusCode) >= 500) {
      return { decision: 1 }; // RECORD_AND_SAMPLED
    }

    // Always trace slow requests (decided later via tail sampling)
    // High-traffic health checks: never
    if (path === "/health" || path === "/metrics") {
      return { decision: 0 }; // NOT_RECORD
    }

    // Payment paths: always trace
    if (path?.startsWith("/api/payments")) {
      return { decision: 1 };
    }

    // Default: 10% sampling
    const hash = traceId
      .slice(-8)
      .split("")
      .reduce((h, c) => h * 31 + c.charCodeAt(0), 0);

    return {
      decision: Math.abs(hash) % 100 < 10 ? 1 : 0,
    };
  }

  toString(): string {
    return "RuleBasedSampler";
  }
}# OTel Collector tail-based sampling
# Decides after seeing the complete trace
processors:
tail_sampling:
decision_wait: 30s
num_traces: 100000
policies:
# Always keep error traces
- name: errors
type: status_code
status_code:
status_codes: [ERROR]
# Always keep slow traces
- name: latency
type: latency
latency:
threshold_ms: 2000
# Sample 5% of normal traffic
- name: probabilistic
type: probabilistic
probabilistic:
sampling_percentage: 5
# Always keep traces from critical services
- name: critical-services
type: string_attribute
string_attribute:
key: service.name
values:
- payment-service
- auth-serviceTail-based sampling in the collector is more powerful than head-based sampling in the SDK because it can see the complete trace before deciding. Error traces, slow traces, and traces from critical paths are always kept, while routine successful requests are sampled probabilistically.
Context Propagation Across Services
Trace context must propagate correctly across every communication boundary. A single service that drops context breaks the trace.
// Context propagation in async message systems
import {
  propagation,
  context,
  trace,
  SpanKind,
} from "@opentelemetry/api";

// Producer: inject trace context into message headers
function publishEvent(
  queue: string,
  payload: Record<string, unknown>
): void {
  const tracer = trace.getTracer("publisher");
  const span = tracer.startSpan("publish", {
    kind: SpanKind.PRODUCER,
    attributes: {
      "messaging.system": "rabbitmq",
      "messaging.destination": queue,
    },
  });

  // Inject current context into message headers
  const headers: Record<string, string> = {};
  propagation.inject(
    trace.setSpan(context.active(), span),
    headers
  );

  channel.publish(queue, {
    body: Buffer.from(JSON.stringify(payload)),
    properties: { headers },
  });

  span.end();
}

// Consumer: extract trace context from message headers
function consumeEvent(message: Message): void {
  // Extract parent context from message headers
  const parentContext = propagation.extract(
    context.active(),
    message.properties.headers
  );

  const tracer = trace.getTracer("consumer");

  // Create consumer span linked to producer
  context.with(parentContext, () => {
    const span = tracer.startSpan("process", {
      kind: SpanKind.CONSUMER,
      attributes: {
        "messaging.system": "rabbitmq",
        "messaging.operation": "process",
      },
    });

    try {
      processMessage(message);
      span.setStatus({ code: 0 }); // OK
    } catch (error) {
      span.setStatus({
        code: 2, // ERROR
        message:
          error instanceof Error
            ? error.message
            : "Unknown error",
      });
      span.recordException(error as Error);
      throw error;
    } finally {
      span.end();
    }
  });
}
Correlating Traces with Logs and Metrics
Traces become truly powerful when correlated with logs and metrics. A trace ID in every log entry lets you jump from a trace to the exact logs for that request.
// Structured logging with trace correlation
import { context, trace } from "@opentelemetry/api";
import pino from "pino";

function createLogger(serviceName: string) {
  const baseLogger = pino({
    level: process.env.LOG_LEVEL ?? "info",
  });

  return {
    info(message: string, data?: Record<string, unknown>) {
      baseLogger.info({
        ...data,
        ...getTraceContext(),
        service: serviceName,
        msg: message,
      });
    },

    error(
      message: string,
      error?: Error,
      data?: Record<string, unknown>
    ) {
      baseLogger.error({
        ...data,
        ...getTraceContext(),
        service: serviceName,
        msg: message,
        error: error
          ? {
              message: error.message,
              stack: error.stack,
              name: error.name,
            }
          : undefined,
      });
    },
  };
}

function getTraceContext(): Record<string, string> {
  const span = trace.getSpan(context.active());
  if (!span) return {};

  const spanContext = span.spanContext();
  return {
    traceId: spanContext.traceId,
    spanId: spanContext.spanId,
    traceFlags: String(spanContext.traceFlags),
  };
}

// Every log entry includes trace_id and span_id
// {"level":"info","traceId":"abc123...","spanId":"def456...",
//  "service":"order-service","msg":"Order created",
//  "orderId":"ord-789"}
Key Takeaways
Auto-instrumentation with OpenTelemetry covers HTTP, database, message queue, and gRPC spans automatically—manual span creation should only be added for business-logic boundaries that auto-instrumentation can't detect. Tail-based sampling in the OTel Collector keeps all error traces, slow traces, and critical-path traces while probabilistically sampling normal traffic, avoiding the blind spots of head-based sampling decisions. Context propagation must cross every communication boundary including message queues—injecting trace context into message headers and extracting it in consumers maintains the trace chain through async workflows. Correlating traces with logs via trace ID in structured log entries lets you jump from a slow span directly to the relevant log lines, combining the "what happened" of traces with the "why" of logs. Batch span processors with tuned queue sizes and export intervals prevent tracing from impacting application performance—spans are buffered and exported asynchronously rather than sent inline with request processing.