Observability-Driven Development
Shift observability left by designing around structured logs, distributed traces and meaningful metrics from day one — faster debugging, shorter incidents.

Observability Is Not Monitoring
Monitoring tells you when something is wrong. Observability tells you why. Monitoring checks known failure modes with predefined thresholds. Observability lets you ask arbitrary questions about system behavior without deploying new code.
The distinction matters because modern distributed systems fail in novel ways. You cannot predict every failure mode in advance, but you can instrument your system so that when something unexpected happens, you can trace the cause in minutes instead of hours.
Structured Logging That Scales
Unstructured logs are grep-able text files. Structured logs are queryable events with typed fields, correlation IDs, and contextual metadata that make debugging across services possible.
// ❌ Unstructured logging — nearly useless at scale
console.log(`User ${userId} failed to checkout: ${error.message}`);

// ✅ Structured logging — queryable, correlatable, actionable
import { Logger } from "./logger";

interface LogContext {
  traceId: string;
  spanId: string;
  service: string;
  environment: string;
}

class StructuredLogger {
  constructor(private readonly context: LogContext) {}

  info(message: string, fields: Record<string, unknown> = {}): void {
    this.emit("info", message, fields);
  }

  error(
    message: string,
    error: Error,
    fields: Record<string, unknown> = {}
  ): void {
    this.emit("error", message, {
      ...fields,
      error: {
        name: error.name,
        message: error.message,
        stack: error.stack,
      },
    });
  }

  private emit(
    level: string,
    message: string,
    fields: Record<string, unknown>
  ): void {
    const entry = {
      timestamp: new Date().toISOString(),
      level,
      message,
      ...this.context,
      ...fields,
    };
    process.stdout.write(JSON.stringify(entry) + "\n");
  }
}

// Usage with request context
function createRequestLogger(req: Request, baseContext: LogContext): StructuredLogger {
  return new StructuredLogger({
    ...baseContext,
    traceId: req.headers["x-trace-id"] as string || generateTraceId(),
    spanId: generateSpanId(),
  });
}
Every log entry carries a trace ID that connects it to every other log and span in the same request flow. When a user reports "my checkout failed," you query by trace ID and see every log from every service involved in that specific request.
Distributed Tracing with OpenTelemetry
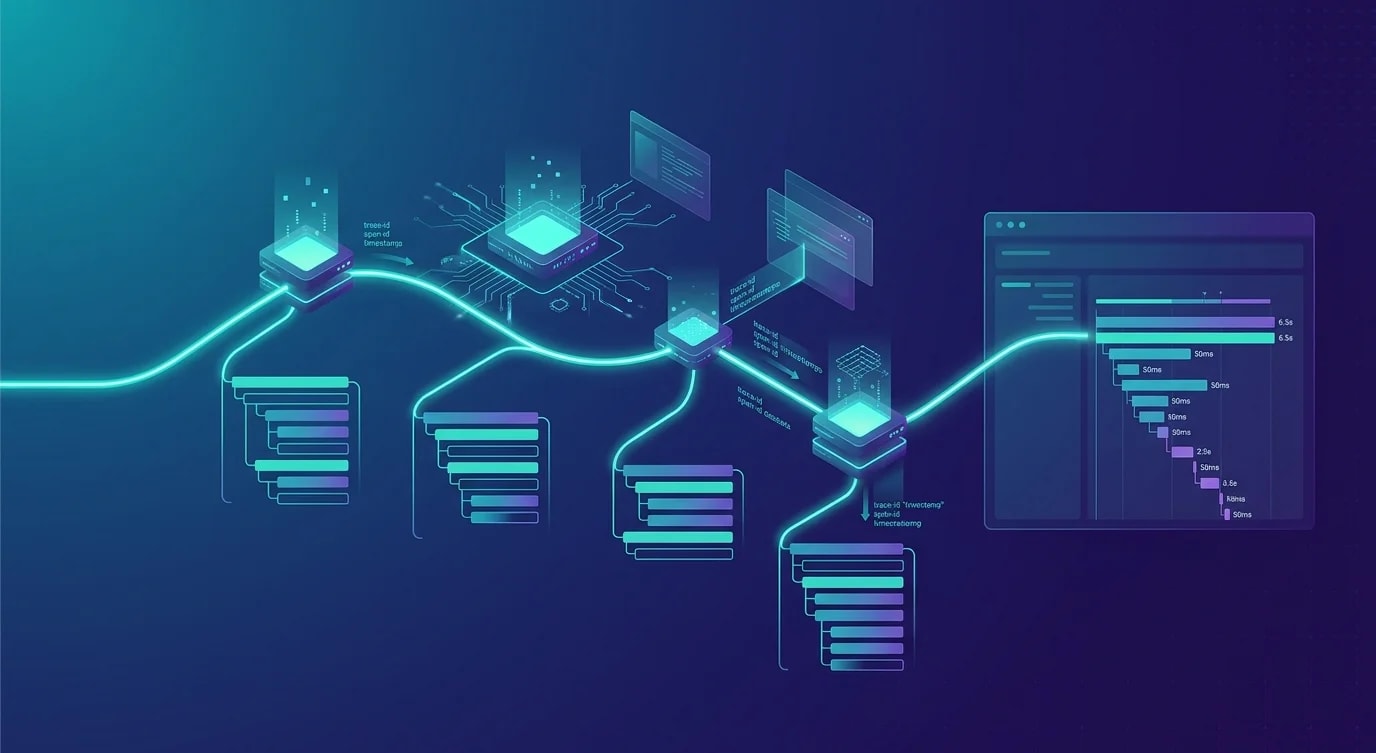
Traces show the complete journey of a request through your system—which services were called, how long each took, where the bottleneck is, and which service errored.
import { trace, SpanStatusCode, context, propagation } from "@opentelemetry/api";

const tracer = trace.getTracer("checkout-service");

async function processCheckout(
  order: Order
): Promise<CheckoutResult> {
  return tracer.startActiveSpan(
    "checkout.process",
    { attributes: { "order.id": order.id, "order.items": order.items.length } },
    async (span) => {
      try {
        // Each step creates a child span
        const inventory = await tracer.startActiveSpan(
          "checkout.verify-inventory",
          async (inventorySpan) => {
            const result = await inventoryService.verify(order.items);
            inventorySpan.setAttribute(
              "inventory.available",
              result.allAvailable
            );
            inventorySpan.end();
            return result;
          }
        );

        if (!inventory.allAvailable) {
          span.setStatus({
            code: SpanStatusCode.ERROR,
            message: "Items out of stock",
          });
          span.end();
          return { success: false, reason: "out-of-stock" };
        }

        const payment = await tracer.startActiveSpan(
          "checkout.process-payment",
          async (paymentSpan) => {
            paymentSpan.setAttribute("payment.method", order.paymentMethod);
            const result = await paymentService.charge(order);
            paymentSpan.setAttribute("payment.status", result.status);
            paymentSpan.end();
            return result;
          }
        );

        span.setStatus({ code: SpanStatusCode.OK });
        span.end();

        return { success: true, transactionId: payment.transactionId };
      } catch (error) {
        span.recordException(error as Error);
        span.setStatus({
          code: SpanStatusCode.ERROR,
          message: (error as Error).message,
        });
        span.end();
        throw error;
      }
    }
  );
}
Metrics That Drive Decisions
Not all metrics are worth collecting. The RED method (Rate, Errors, Duration) for services and the USE method (Utilization, Saturation, Errors) for resources cover the critical ground without drowning you in dashboards nobody watches.
import { metrics } from "@opentelemetry/api";

const meter = metrics.getMeter("checkout-service");

// RED metrics for the checkout endpoint
const checkoutCounter = meter.createCounter("checkout.requests.total", {
  description: "Total checkout requests",
});

const checkoutErrors = meter.createCounter("checkout.errors.total", {
  description: "Total checkout errors",
});

const checkoutDuration = meter.createHistogram("checkout.duration.ms", {
  description: "Checkout request duration in milliseconds",
  unit: "ms",
});

// USE metrics for the connection pool
const poolUtilization = meter.createObservableGauge(
  "db.pool.utilization",
  { description: "Database pool utilization ratio" }
);

poolUtilization.addCallback((result) => {
  const pool = getConnectionPool();
  result.observe(pool.activeConnections / pool.maxConnections, {
    pool: "primary",
  });
});

// Middleware to instrument every request
function instrumentRequest(
  handler: RequestHandler
): RequestHandler {
  return async (req, res) => {
    const start = Date.now();
    const attributes = {
      "http.method": req.method,
      "http.route": req.route?.path || "unknown",
    };

    try {
      const result = await handler(req, res);
      checkoutCounter.add(1, { ...attributes, "http.status": res.statusCode });
      return result;
    } catch (error) {
      checkoutErrors.add(1, {
        ...attributes,
        "error.type": (error as Error).name,
      });
      throw error;
    } finally {
      checkoutDuration.record(Date.now() - start, attributes);
    }
  };
}
Correlation: Connecting the Three Pillars
The power of observability comes from correlation—jumping from an anomalous metric to the specific traces that caused it, then from traces to the specific logs within those traces. This requires a shared identifier: the trace ID.
interface ObservabilityContext {
  traceId: string;
  spanId: string;
  serviceName: string;
  environment: string;
}

// Inject context into every outgoing request
async function instrumentedFetch(
  url: string,
  options: RequestInit,
  ctx: ObservabilityContext
): Promise<Response> {
  const headers = new Headers(options.headers);
  headers.set("x-trace-id", ctx.traceId);
  headers.set("x-span-id", ctx.spanId);
  headers.set("x-service-name", ctx.serviceName);

  const start = Date.now();
  const response = await fetch(url, { ...options, headers });
  const duration = Date.now() - start;

  // Log with full context
  const logger = new StructuredLogger(ctx);
  logger.info("outgoing_request", {
    url,
    method: options.method || "GET",
    statusCode: response.status,
    durationMs: duration,
  });

  return response;
}

// Query workflow: metric spike → traces → logs
// 1. Alert: checkout.errors.total spike at 14:32
// 2. Query traces: find all traces with error status between 14:30-14:35
// 3. Identify pattern: all errors come from payment-service
// 4. Query logs: filter by traceId of failed requests
// 5. Root cause: payment gateway returning 503 due to certificate expiry
SLOs as Observability Contracts
Service Level Objectives turn observability data into actionable contracts. Instead of reacting to every error, you define acceptable error budgets and prioritize engineering work based on budget burn rate.
interface SLO {
  name: string;
  target: number;           // e.g., 0.999 for 99.9%
  window: "7d" | "28d";
  indicator: SLI;
}

interface SLI {
  good: string;    // Query for successful events
  total: string;   // Query for all events
}

const checkoutSLO: SLO = {
  name: "Checkout Success Rate",
  target: 0.999,
  window: "28d",
  indicator: {
    good: "sum(checkout_requests_total{status='success'})",
    total: "sum(checkout_requests_total)",
  },
};

function calculateErrorBudget(
  slo: SLO,
  currentGoodEvents: number,
  currentTotalEvents: number
): {
  budgetTotal: number;
  budgetConsumed: number;
  budgetRemaining: number;
  burnRate: number;
} {
  const allowedFailureRate = 1 - slo.target;
  const budgetTotal = currentTotalEvents * allowedFailureRate;
  const actualFailures = currentTotalEvents - currentGoodEvents;
  const budgetConsumed = actualFailures;

  return {
    budgetTotal: Math.floor(budgetTotal),
    budgetConsumed,
    budgetRemaining: Math.floor(budgetTotal - budgetConsumed),
    burnRate: budgetConsumed / budgetTotal,
  };
}
Key Takeaways
Observability is not something you bolt on after launch—it is a design discipline that starts before the first line of application code. Structure your logs with typed fields and correlation IDs from day one. Instrument distributed traces at service boundaries so you can follow any request through the entire system. Collect RED metrics for services and USE metrics for resources.
The correlation layer is what transforms three separate data streams into a single debugging workflow: a metric anomaly leads to specific traces, which lead to specific logs, which reveal the root cause. Without correlation, you have three tools that each tell part of the story. With it, you have one system that tells the whole story.
Define SLOs early. They turn observability data into prioritization decisions—when the error budget is healthy, ship features; when it is burning fast, fix reliability. This simple framework prevents teams from oscillating between "ignore all errors" and "drop everything for every alert."