Backend
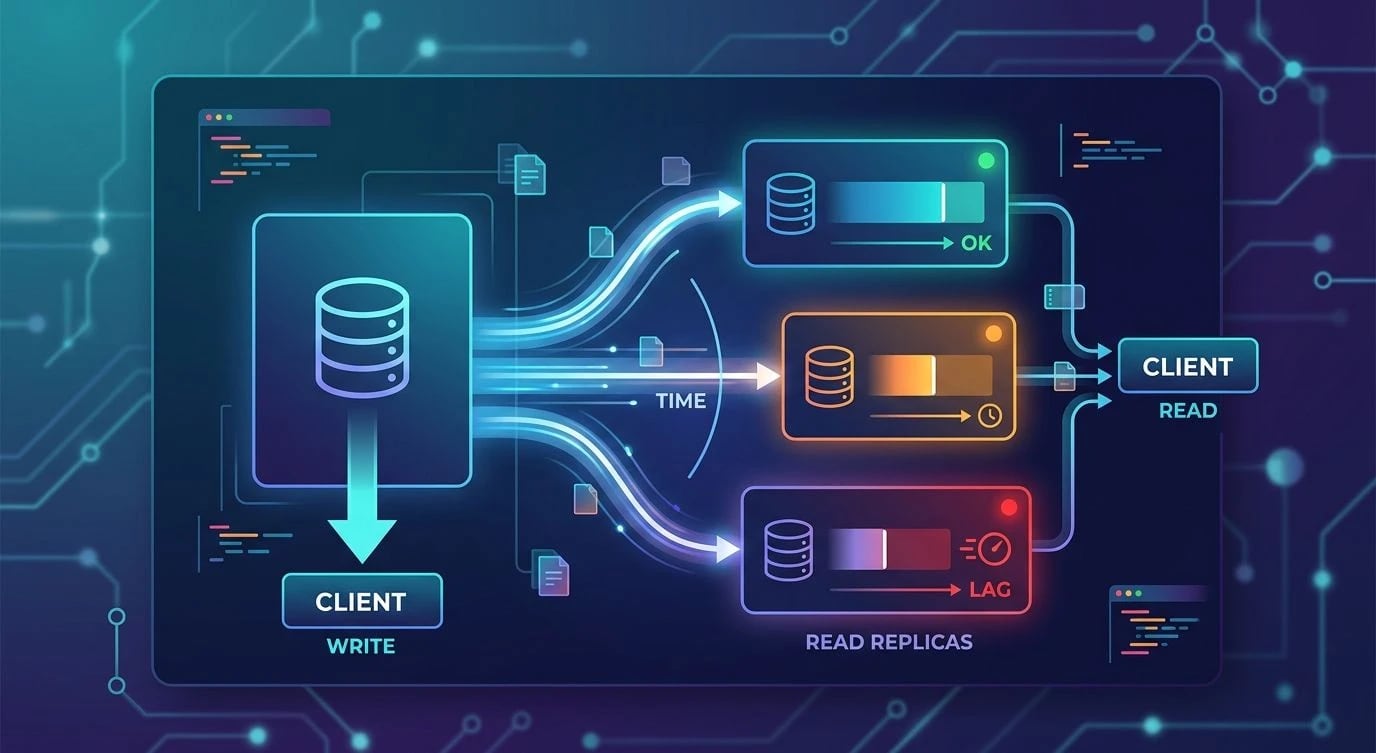
Replication Lag: The Hidden Cost of Read Replicas
Why read replicas introduce stale reads, how replication lag breaks consistency assumptions, and practical patterns to handle it safely.
·4 min read
Categories
APIs & server logic · 57 articles · Page 1 of 5
Why read replicas introduce stale reads, how replication lag breaks consistency assumptions, and practical patterns to handle it safely.
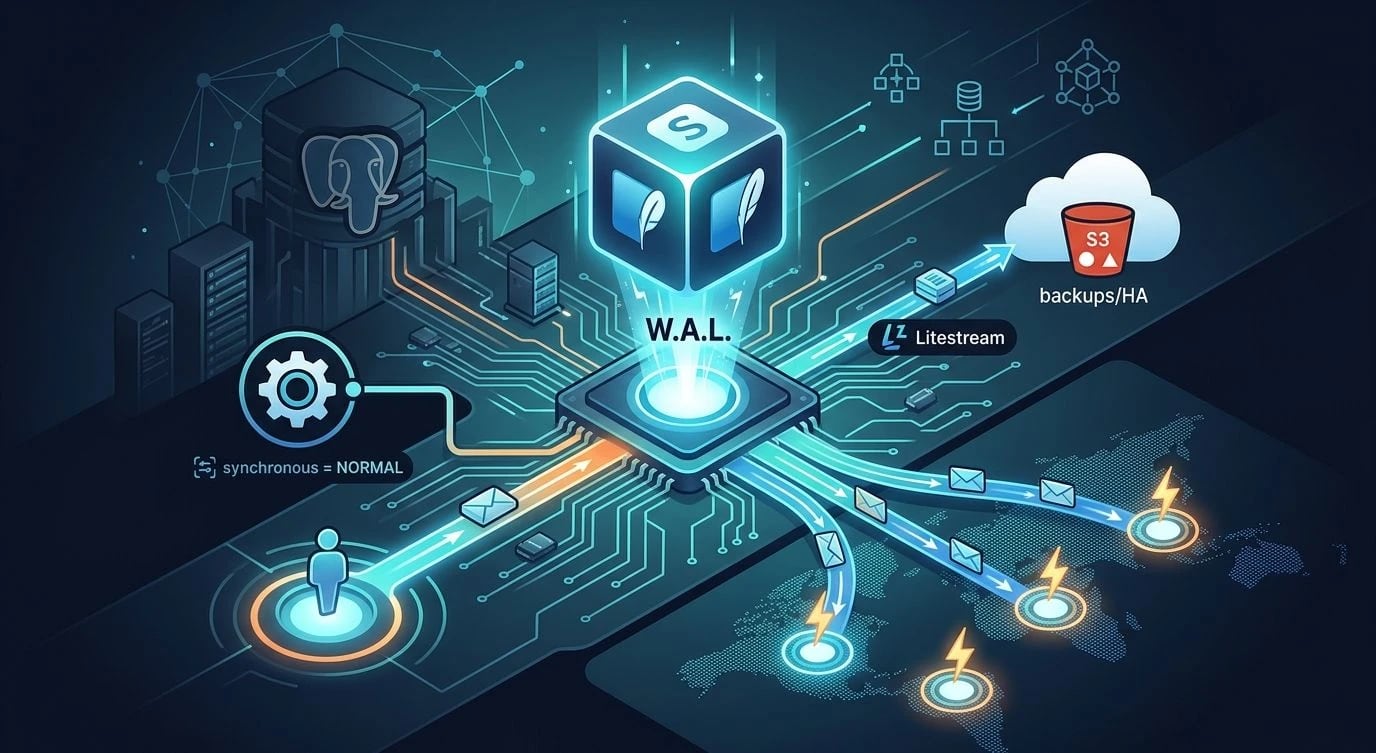
Not just for mobile apps: with WAL mode and the right replication strategy, SQLite runs production workloads with less operational overhead than Postgres.
HTTP/3 replaces TCP with QUIC over UDP, eliminating head-of-line blocking at the transport layer — here's what actually changes for your services.
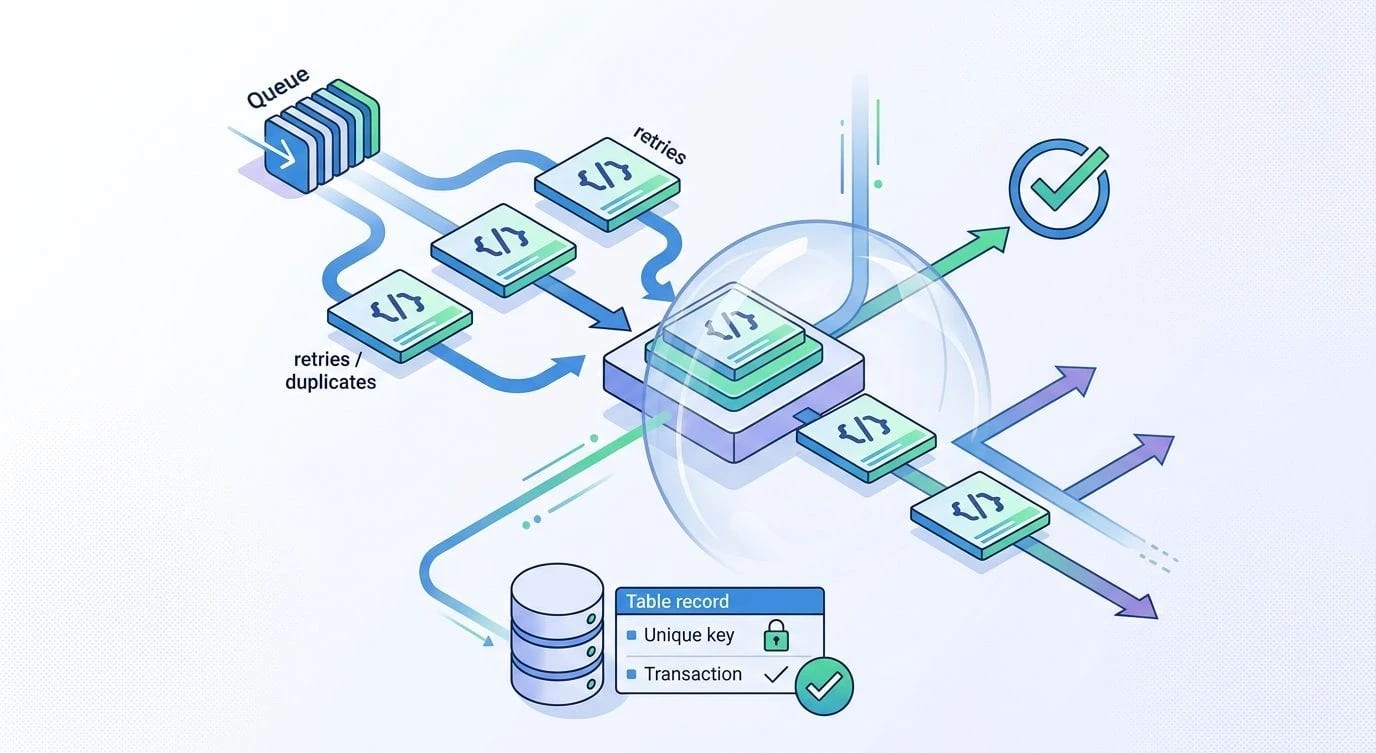
Exactly-once processing does not exist in distributed systems — here is how to design background jobs that survive retries, crashes and duplicate deliveries.

How to use materialized views to speed up expensive aggregations in Postgres without silently serving stale data to your users.
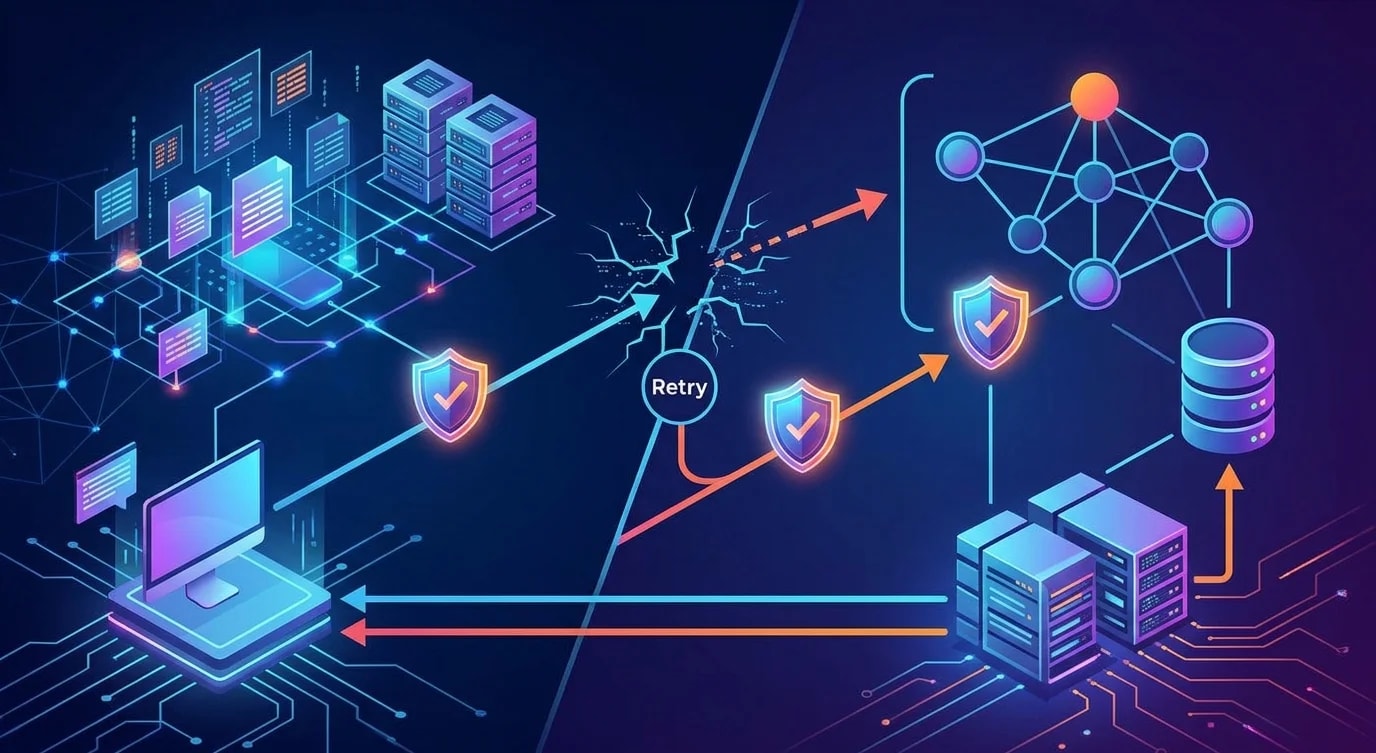
How to design and implement idempotency keys so retried requests never double-charge, double-send, or double-create resources.

Soft deletes look like a simple safety net, but they silently corrupt your schema, poison your queries, and break your constraints — here's what to use instead.

When a cache entry expires under load, dozens of requests race to rebuild it — inflight deduplication collapses that stampede into one upstream call.

Postgres has a powerful built-in full-text search engine using tsvector, tsquery, and GIN indexes — no Elasticsearch cluster required for most applications.
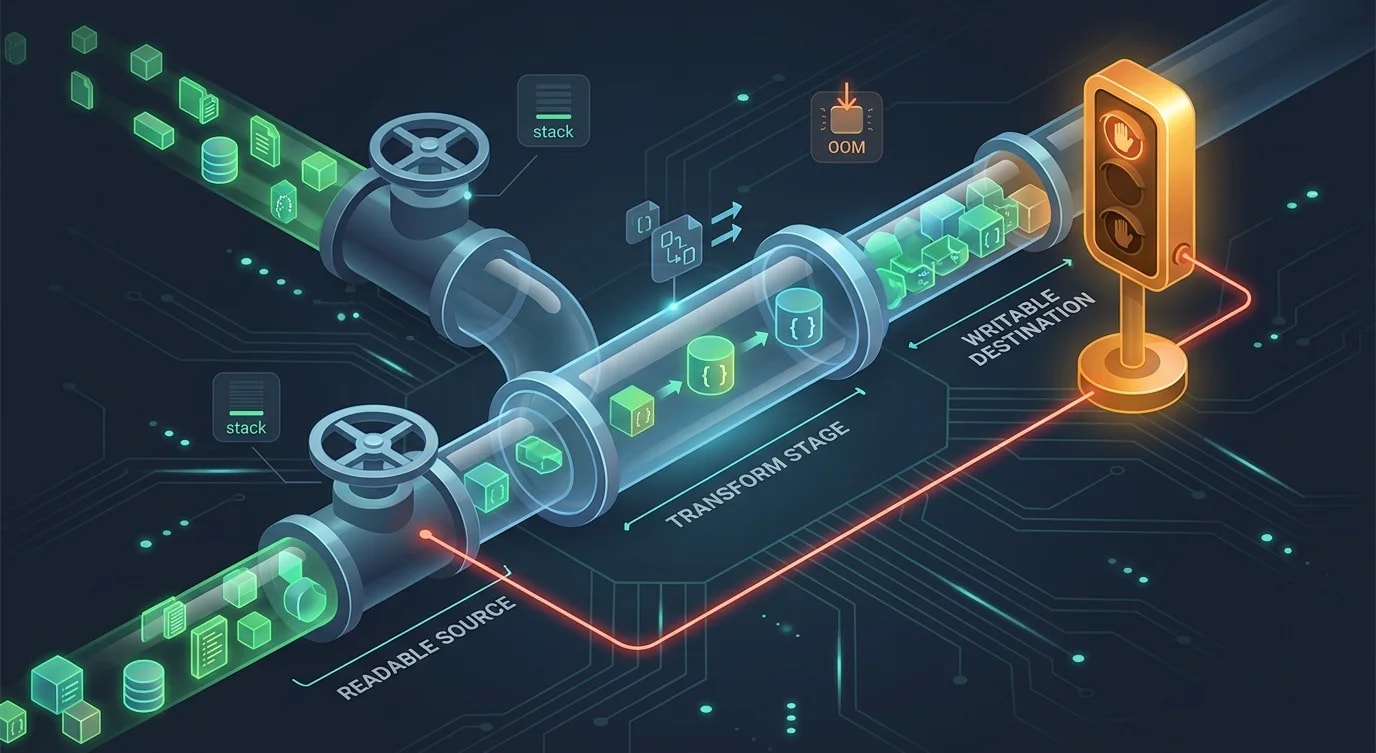
Stop loading entire result sets into memory: how Node.js streams and async generators let you process millions of records without blowing the heap.

Stop racing conditions in distributed systems: a practical guide to implementing distributed locks with Redis and PostgreSQL advisory locks in Node.js.

Replace Node's stringly-typed EventEmitter with a generic typed alternative that catches event name typos and payload mismatches at compile time.