Fault-Tolerant Systems with Graceful Degradation
Fault tolerance engineering in practice: circuit breakers, bulkheads, fallback chains and degradation strategies that keep systems useful when parts fail.
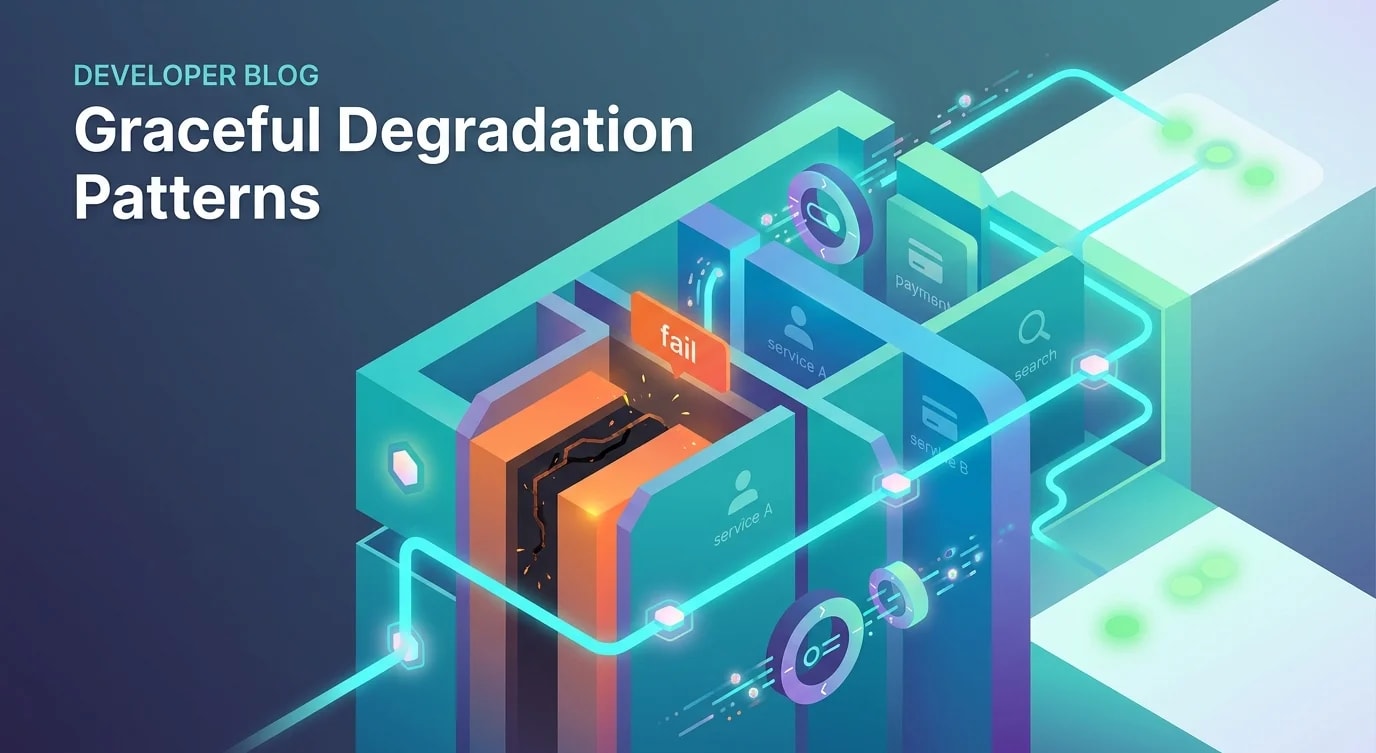
The Difference Between Failure and Outage
Every system fails. The distinction between a resilient system and a fragile one is not whether failures occur, but whether failures in individual components cascade into complete outages. A payment service going down should not prevent users from browsing products. A recommendation engine timing out should not block the checkout flow.
Graceful degradation is the practice of designing systems that remain useful—even if reduced in capability—when parts of them fail. It requires thinking about failure modes during design, not as an afterthought during incident response.
Circuit Breaker Implementation
The circuit breaker pattern prevents a failing dependency from consuming resources and cascading failures to healthy components. When a service starts failing, the circuit opens and returns fallback responses immediately instead of waiting for timeouts.
enum CircuitState {
  CLOSED = "CLOSED",
  OPEN = "OPEN",
  HALF_OPEN = "HALF_OPEN",
}

interface CircuitBreakerConfig {
  failureThreshold: number;
  resetTimeout: number;
  halfOpenRequests: number;
}

class CircuitBreaker<T> {
  private state: CircuitState = CircuitState.CLOSED;
  private failureCount = 0;
  private lastFailureTime = 0;
  private halfOpenAttempts = 0;

  constructor(
    private readonly action: () => Promise<T>,
    private readonly fallback: () => T,
    private readonly config: CircuitBreakerConfig
  ) {}

  async execute(): Promise<T> {
    if (this.state === CircuitState.OPEN) {
      if (Date.now() - this.lastFailureTime > this.config.resetTimeout) {
        this.state = CircuitState.HALF_OPEN;
        this.halfOpenAttempts = 0;
      } else {
        return this.fallback();
      }
    }

    try {
      const result = await this.action();
      this.onSuccess();
      return result;
    } catch (error) {
      this.onFailure();
      return this.fallback();
    }
  }

  private onSuccess(): void {
    this.failureCount = 0;
    if (this.state === CircuitState.HALF_OPEN) {
      this.halfOpenAttempts++;
      if (this.halfOpenAttempts >= this.config.halfOpenRequests) {
        this.state = CircuitState.CLOSED;
      }
    }
  }

  private onFailure(): void {
    this.failureCount++;
    this.lastFailureTime = Date.now();
    if (this.failureCount >= this.config.failureThreshold) {
      this.state = CircuitState.OPEN;
    }
  }

  getState(): CircuitState {
    return this.state;
  }
}
The circuit breaker operates in three states: closed (normal operation), open (all requests short-circuit to fallback), and half-open (limited test requests to check if the service has recovered).
Bulkhead Pattern for Resource Isolation
Bulkheads isolate failures by partitioning resources so that a problem in one area cannot exhaust resources needed by another.
// ❌ Shared connection pool — one slow service blocks everything
class SharedPool {
  private connections = 0;
  private readonly maxConnections = 100;

  async request(service: string): Promise<Response> {
    if (this.connections >= this.maxConnections) {
      throw new Error("Pool exhausted — ALL services affected");
    }
    this.connections++;
    try {
      return await fetch(`https://${service}/api`);
    } finally {
      this.connections--;
    }
  }
}

// ✅ Bulkheaded pools — failures are contained per service
interface BulkheadConfig {
  maxConcurrent: number;
  queueSize: number;
}

class Bulkhead {
  private active = 0;
  private queue: Array<() => void> = [];

  constructor(
    private readonly name: string,
    private readonly config: BulkheadConfig
  ) {}

  async execute<T>(fn: () => Promise<T>): Promise<T> {
    if (this.active >= this.config.maxConcurrent) {
      if (this.queue.length >= this.config.queueSize) {
        throw new Error(
          `Bulkhead '${this.name}' full: ${this.active} active, ${this.queue.length} queued`
        );
      }

      await new Promise<void>((resolve) => {
        this.queue.push(resolve);
      });
    }

    this.active++;
    try {
      return await fn();
    } finally {
      this.active--;
      const next = this.queue.shift();
      if (next) next();
    }
  }
}

// Each service gets its own resource budget
const bulkheads = {
  payments: new Bulkhead("payments", { maxConcurrent: 30, queueSize: 10 }),
  inventory: new Bulkhead("inventory", { maxConcurrent: 20, queueSize: 50 }),
  recommendations: new Bulkhead("recommendations", {
    maxConcurrent: 10,
    queueSize: 5,
  }),
};
When the recommendation service slows down, it can only consume its allocated 10 concurrent connections. Payments and inventory continue operating normally with their own pools.
Fallback Chain Architecture
A single fallback is rarely sufficient. Production systems need layered fallback strategies that try progressively simpler approaches before giving up entirely.
interface FallbackStep<T> {
  name: string;
  execute: () => Promise<T>;
  timeout: number;
}

async function executeFallbackChain<T>(
  steps: FallbackStep<T>[],
  onStepFailed?: (step: string, error: Error) => void
): Promise<T> {
  for (const step of steps) {
    try {
      const result = await Promise.race([
        step.execute(),
        new Promise<never>((_, reject) =>
          setTimeout(() => reject(new Error("Timeout")), step.timeout)
        ),
      ]);
      return result;
    } catch (error) {
      onStepFailed?.(step.name, error as Error);
      continue;
    }
  }
  throw new Error("All fallback steps exhausted");
}

// Product pricing with layered fallbacks
interface ProductPrice {
  amount: number;
  currency: string;
  source: string;
}

const pricingChain: FallbackStep<ProductPrice>[] = [
  {
    name: "real-time-pricing-service",
    execute: async () => {
      const res = await fetch("https://pricing.internal/api/price");
      return { ...(await res.json()), source: "real-time" };
    },
    timeout: 500,
  },
  {
    name: "cached-pricing",
    execute: async () => {
      const cached = await redis.get("product:price:123");
      if (!cached) throw new Error("Cache miss");
      return { ...JSON.parse(cached), source: "cache" };
    },
    timeout: 100,
  },
  {
    name: "last-known-price-from-db",
    execute: async () => {
      const row = await db.query("SELECT price FROM products WHERE id = $1", [
        123,
      ]);
      return { amount: row.price, currency: "USD", source: "database" };
    },
    timeout: 2000,
  },
];
The fallback chain degrades from real-time pricing to cached pricing to database pricing. Each step is progressively slower but more reliable. The consumer receives the best available data with a source field indicating the freshness.
Feature Degradation Mapping
Not all features are equally important. Map your system's features by business criticality and define degraded modes for each tier.
enum FeatureTier {
  CRITICAL = "critical",
  IMPORTANT = "important",
  NICE_TO_HAVE = "nice-to-have",
}

interface FeatureDegradationPlan {
  feature: string;
  tier: FeatureTier;
  normalBehavior: string;
  degradedBehavior: string;
  dependencies: string[];
}

const degradationPlan: FeatureDegradationPlan[] = [
  {
    feature: "Checkout",
    tier: FeatureTier.CRITICAL,
    normalBehavior: "Full payment processing with fraud detection",
    degradedBehavior: "Process payments, skip fraud scoring, flag for manual review",
    dependencies: ["payment-gateway", "fraud-service", "inventory-service"],
  },
  {
    feature: "Product search",
    tier: FeatureTier.IMPORTANT,
    normalBehavior: "Full-text search with personalized ranking",
    degradedBehavior: "Basic search without personalization, category browsing only",
    dependencies: ["search-service", "personalization-engine"],
  },
  {
    feature: "Recommendations",
    tier: FeatureTier.NICE_TO_HAVE,
    normalBehavior: "ML-powered personalized recommendations",
    degradedBehavior: "Show trending/popular items from static cache",
    dependencies: ["recommendation-service", "user-profile-service"],
  },
];

function getActiveFeatures(
  healthyServices: Set<string>
): Map<string, string> {
  const activeFeatures = new Map<string, string>();

  for (const plan of degradationPlan) {
    const allHealthy = plan.dependencies.every((dep) =>
      healthyServices.has(dep)
    );

    const criticalDepsHealthy = plan.dependencies
      .slice(0, 1)
      .every((dep) => healthyServices.has(dep));

    if (allHealthy) {
      activeFeatures.set(plan.feature, "normal");
    } else if (criticalDepsHealthy || plan.tier === FeatureTier.CRITICAL) {
      activeFeatures.set(plan.feature, "degraded");
    } else {
      activeFeatures.set(plan.feature, "disabled");
    }
  }

  return activeFeatures;
}
Health Checking and Dependency Monitoring
Proactive health checking enables graceful degradation before users experience failures.
interface HealthCheckResult {
  service: string;
  status: "healthy" | "degraded" | "unhealthy";
  latencyMs: number;
  lastChecked: Date;
  consecutiveFailures: number;
}

class DependencyMonitor {
  private results = new Map<string, HealthCheckResult>();
  private intervals = new Map<string, NodeJS.Timeout>();

  registerCheck(
    service: string,
    check: () => Promise<void>,
    intervalMs: number
  ): void {
    const runCheck = async (): Promise<void> => {
      const start = Date.now();
      const previous = this.results.get(service);

      try {
        await Promise.race([
          check(),
          new Promise<never>((_, reject) =>
            setTimeout(() => reject(new Error("Health check timeout")), 5000)
          ),
        ]);

        this.results.set(service, {
          service,
          status: "healthy",
          latencyMs: Date.now() - start,
          lastChecked: new Date(),
          consecutiveFailures: 0,
        });
      } catch {
        const failures = (previous?.consecutiveFailures ?? 0) + 1;
        this.results.set(service, {
          service,
          status: failures >= 3 ? "unhealthy" : "degraded",
          latencyMs: Date.now() - start,
          lastChecked: new Date(),
          consecutiveFailures: failures,
        });
      }
    };

    runCheck();
    this.intervals.set(service, setInterval(runCheck, intervalMs));
  }

  getHealthyServices(): Set<string> {
    const healthy = new Set<string>();
    for (const [service, result] of this.results) {
      if (result.status !== "unhealthy") {
        healthy.add(service);
      }
    }
    return healthy;
  }

  shutdown(): void {
    for (const interval of this.intervals.values()) {
      clearInterval(interval);
    }
  }
}
Key Takeaways
Fault tolerance is a design choice, not a deployment concern. Circuit breakers prevent cascading failures by short-circuiting calls to unhealthy services. Bulkheads isolate resource consumption so that one failing dependency cannot exhaust the resources needed by others. Fallback chains provide progressively simpler responses when primary sources are unavailable.
Map your features by business criticality and define acceptable degraded states for each. The goal is not perfect uptime for every feature—it is ensuring that critical paths remain functional even when supporting services fail. A system that continues to process orders with degraded recommendations is infinitely more valuable than one that goes completely dark because the recommendation engine timed out.