Fehlertolerante Systeme mit Graceful Degradation
Fehlertoleranz in der Praxis: Circuit Breaker, Bulkheads, Fallback-Ketten und Degradationsstrategien, die Systeme bei Teilausfällen nutzbar halten.
Der Unterschied zwischen Fehler und Ausfall
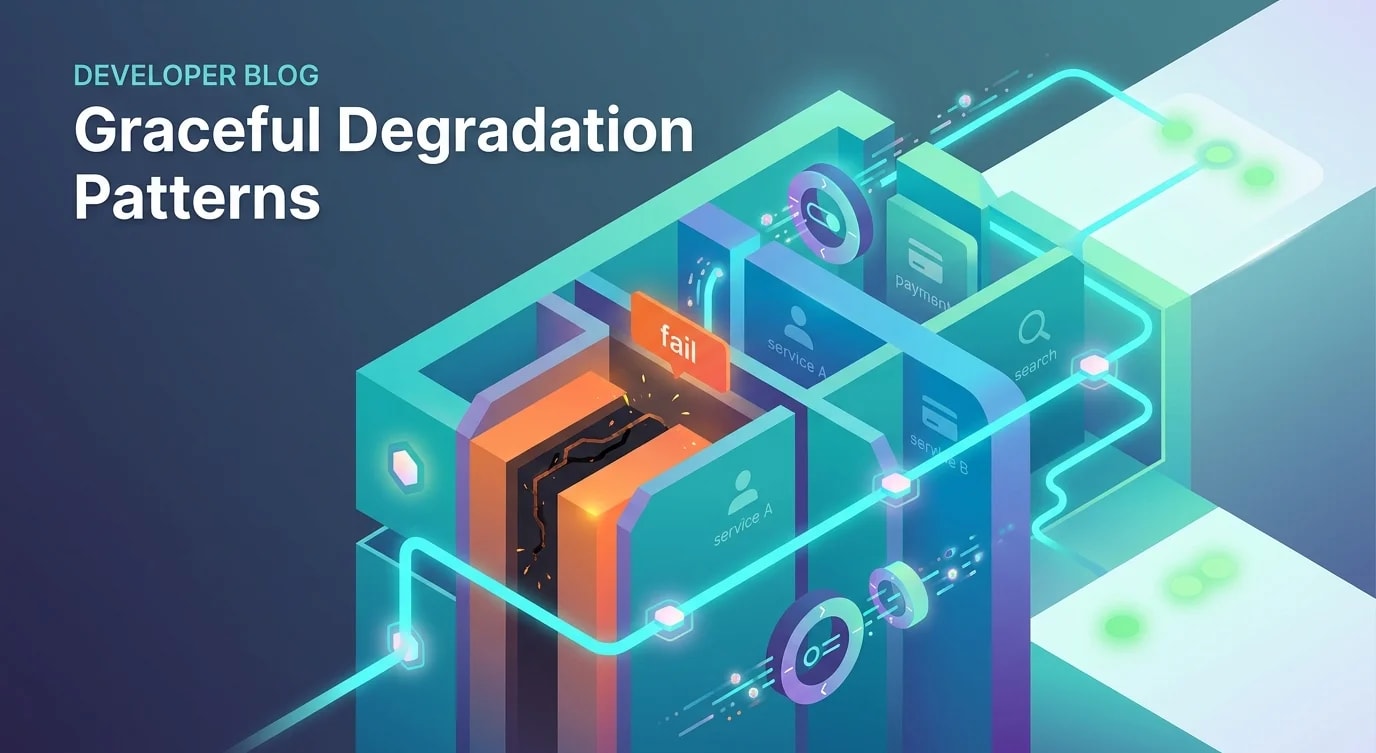
Jedes System versagt irgendwann. Der Unterschied zwischen einem resilienten und einem fragilen System liegt nicht darin, ob Fehler auftreten, sondern ob Fehler einzelner Komponenten sich zu kompletten Ausfällen ausbreiten. Wenn ein Zahlungsdienst ausfällt, sollten Nutzer weiterhin Produkte durchsuchen können. Wenn eine Empfehlungsengine in ein Timeout läuft, sollte der Checkout-Fluss nicht blockiert werden.
Graceful Degradation bedeutet, Systeme so zu entwerfen, dass sie auch bei Teilausfällen nützlich bleiben — selbst wenn ihre Fähigkeiten eingeschränkt sind. Dazu muss man Fehlermodi bereits beim Design berücksichtigen, nicht erst nachträglich im Incident Response.
Implementierung des Circuit Breakers
Das Circuit-Breaker-Muster verhindert, dass eine ausgefallene Abhängigkeit Ressourcen verbraucht und Fehler auf gesunde Komponenten überträgt. Wenn ein Service ausfällt, öffnet sich der Circuit und liefert sofort Fallback-Antworten, anstatt auf Timeouts zu warten.
enum CircuitState {
  CLOSED = "CLOSED",
  OPEN = "OPEN",
  HALF_OPEN = "HALF_OPEN",
}

interface CircuitBreakerConfig {
  failureThreshold: number;
  resetTimeout: number;
  halfOpenRequests: number;
}

class CircuitBreaker<T> {
  private state: CircuitState = CircuitState.CLOSED;
  private failureCount = 0;
  private lastFailureTime = 0;
  private halfOpenAttempts = 0;

  constructor(
    private readonly action: () => Promise<T>,
    private readonly fallback: () => T,
    private readonly config: CircuitBreakerConfig
  ) {}

  async execute(): Promise<T> {
    if (this.state === CircuitState.OPEN) {
      if (Date.now() - this.lastFailureTime > this.config.resetTimeout) {
        this.state = CircuitState.HALF_OPEN;
        this.halfOpenAttempts = 0;
      } else {
        return this.fallback();
      }
    }

    try {
      const result = await this.action();
      this.onSuccess();
      return result;
    } catch (error) {
      this.onFailure();
      return this.fallback();
    }
  }

  private onSuccess(): void {
    this.failureCount = 0;
    if (this.state === CircuitState.HALF_OPEN) {
      this.halfOpenAttempts++;
      if (this.halfOpenAttempts >= this.config.halfOpenRequests) {
        this.state = CircuitState.CLOSED;
      }
    }
  }

  private onFailure(): void {
    this.failureCount++;
    this.lastFailureTime = Date.now();
    if (this.failureCount >= this.config.failureThreshold) {
      this.state = CircuitState.OPEN;
    }
  }

  getState(): CircuitState {
    return this.state;
  }
}
Der Circuit Breaker arbeitet in drei Zuständen: closed (Normalbetrieb), open (alle Anfragen werden auf den Fallback umgeleitet) und half-open (limitierte Testanfragen, um zu prüfen, ob sich der Service erholt hat).
Bulkhead-Muster zur Ressourcenisolierung
Bulkheads isolieren Fehler, indem sie Ressourcen partitionieren, sodass ein Problem in einem Bereich die Ressourcen eines anderen nicht ausschöpfen kann.
// ❌ Shared connection pool — one slow service blocks everything
class SharedPool {
  private connections = 0;
  private readonly maxConnections = 100;

  async request(service: string): Promise<Response> {
    if (this.connections >= this.maxConnections) {
      throw new Error("Pool exhausted — ALL services affected");
    }
    this.connections++;
    try {
      return await fetch(`https://${service}/api`);
    } finally {
      this.connections--;
    }
  }
}

// ✅ Bulkheaded pools — failures are contained per service
interface BulkheadConfig {
  maxConcurrent: number;
  queueSize: number;
}

class Bulkhead {
  private active = 0;
  private queue: Array<() => void> = [];

  constructor(
    private readonly name: string,
    private readonly config: BulkheadConfig
  ) {}

  async execute<T>(fn: () => Promise<T>): Promise<T> {
    if (this.active >= this.config.maxConcurrent) {
      if (this.queue.length >= this.config.queueSize) {
        throw new Error(
          `Bulkhead '${this.name}' full: ${this.active} active, ${this.queue.length} queued`
        );
      }

      await new Promise<void>((resolve) => {
        this.queue.push(resolve);
      });
    }

    this.active++;
    try {
      return await fn();
    } finally {
      this.active--;
      const next = this.queue.shift();
      if (next) next();
    }
  }
}

// Each service gets its own resource budget
const bulkheads = {
  payments: new Bulkhead("payments", { maxConcurrent: 30, queueSize: 10 }),
  inventory: new Bulkhead("inventory", { maxConcurrent: 20, queueSize: 50 }),
  recommendations: new Bulkhead("recommendations", {
    maxConcurrent: 10,
    queueSize: 5,
  }),
};
Wenn die Empfehlungsengine langsamer wird, kann sie nur ihre zugewiesenen 10 gleichzeitigen Verbindungen verbrauchen. Zahlungen und Bestand arbeiten mit ihren eigenen Pools normal weiter.
Fallback-Chain-Architektur
Ein einzelner Fallback reicht selten aus. Produktivsysteme brauchen geschichtete Fallback-Strategien, die schrittweise einfachere Ansätze ausprobieren, bevor sie ganz aufgeben.
interface FallbackStep<T> {
  name: string;
  execute: () => Promise<T>;
  timeout: number;
}

async function executeFallbackChain<T>(
  steps: FallbackStep<T>[],
  onStepFailed?: (step: string, error: Error) => void
): Promise<T> {
  for (const step of steps) {
    try {
      const result = await Promise.race([
        step.execute(),
        new Promise<never>((_, reject) =>
          setTimeout(() => reject(new Error("Timeout")), step.timeout)
        ),
      ]);
      return result;
    } catch (error) {
      onStepFailed?.(step.name, error as Error);
      continue;
    }
  }
  throw new Error("All fallback steps exhausted");
}

// Product pricing with layered fallbacks
interface ProductPrice {
  amount: number;
  currency: string;
  source: string;
}

const pricingChain: FallbackStep<ProductPrice>[] = [
  {
    name: "real-time-pricing-service",
    execute: async () => {
      const res = await fetch("https://pricing.internal/api/price");
      return { ...(await res.json()), source: "real-time" };
    },
    timeout: 500,
  },
  {
    name: "cached-pricing",
    execute: async () => {
      const cached = await redis.get("product:price:123");
      if (!cached) throw new Error("Cache miss");
      return { ...JSON.parse(cached), source: "cache" };
    },
    timeout: 100,
  },
  {
    name: "last-known-price-from-db",
    execute: async () => {
      const row = await db.query("SELECT price FROM products WHERE id = $1", [
        123,
      ]);
      return { amount: row.price, currency: "USD", source: "database" };
    },
    timeout: 2000,
  },
];
Die Fallback-Kette degradiert von Echtzeitpreisen über gecachte Preise bis hin zu Datenbankpreisen. Jeder Schritt ist langsamer, aber zuverlässiger. Der Consumer erhält die besten verfügbaren Daten mit einem source-Feld, das die Aktualität anzeigt.
Feature-Degradation-Mapping
Nicht alle Features sind gleich wichtig. Ordne deine Systemfeatures nach geschäftlicher Kritikalität und definiere abgestufte Modi für jede Ebene.
enum FeatureTier {
  CRITICAL = "critical",
  IMPORTANT = "important",
  NICE_TO_HAVE = "nice-to-have",
}

interface FeatureDegradationPlan {
  feature: string;
  tier: FeatureTier;
  normalBehavior: string;
  degradedBehavior: string;
  dependencies: string[];
}

const degradationPlan: FeatureDegradationPlan[] = [
  {
    feature: "Checkout",
    tier: FeatureTier.CRITICAL,
    normalBehavior: "Full payment processing with fraud detection",
    degradedBehavior: "Process payments, skip fraud scoring, flag for manual review",
    dependencies: ["payment-gateway", "fraud-service", "inventory-service"],
  },
  {
    feature: "Product search",
    tier: FeatureTier.IMPORTANT,
    normalBehavior: "Full-text search with personalized ranking",
    degradedBehavior: "Basic search without personalization, category browsing only",
    dependencies: ["search-service", "personalization-engine"],
  },
  {
    feature: "Recommendations",
    tier: FeatureTier.NICE_TO_HAVE,
    normalBehavior: "ML-powered personalized recommendations",
    degradedBehavior: "Show trending/popular items from static cache",
    dependencies: ["recommendation-service", "user-profile-service"],
  },
];

function getActiveFeatures(
  healthyServices: Set<string>
): Map<string, string> {
  const activeFeatures = new Map<string, string>();

  for (const plan of degradationPlan) {
    const allHealthy = plan.dependencies.every((dep) =>
      healthyServices.has(dep)
    );

    const criticalDepsHealthy = plan.dependencies
      .slice(0, 1)
      .every((dep) => healthyServices.has(dep));

    if (allHealthy) {
      activeFeatures.set(plan.feature, "normal");
    } else if (criticalDepsHealthy || plan.tier === FeatureTier.CRITICAL) {
      activeFeatures.set(plan.feature, "degraded");
    } else {
      activeFeatures.set(plan.feature, "disabled");
    }
  }

  return activeFeatures;
}
Health Checking und Dependency Monitoring
Proaktives Health Checking ermöglicht Graceful Degradation, bevor Nutzer Fehler bemerken.
interface HealthCheckResult {
  service: string;
  status: "healthy" | "degraded" | "unhealthy";
  latencyMs: number;
  lastChecked: Date;
  consecutiveFailures: number;
}

class DependencyMonitor {
  private results = new Map<string, HealthCheckResult>();
  private intervals = new Map<string, NodeJS.Timeout>();

  registerCheck(
    service: string,
    check: () => Promise<void>,
    intervalMs: number
  ): void {
    const runCheck = async (): Promise<void> => {
      const start = Date.now();
      const previous = this.results.get(service);

      try {
        await Promise.race([
          check(),
          new Promise<never>((_, reject) =>
            setTimeout(() => reject(new Error("Health check timeout")), 5000)
          ),
        ]);

        this.results.set(service, {
          service,
          status: "healthy",
          latencyMs: Date.now() - start,
          lastChecked: new Date(),
          consecutiveFailures: 0,
        });
      } catch {
        const failures = (previous?.consecutiveFailures ?? 0) + 1;
        this.results.set(service, {
          service,
          status: failures >= 3 ? "unhealthy" : "degraded",
          latencyMs: Date.now() - start,
          lastChecked: new Date(),
          consecutiveFailures: failures,
        });
      }
    };

    runCheck();
    this.intervals.set(service, setInterval(runCheck, intervalMs));
  }

  getHealthyServices(): Set<string> {
    const healthy = new Set<string>();
    for (const [service, result] of this.results) {
      if (result.status !== "unhealthy") {
        healthy.add(service);
      }
    }
    return healthy;
  }

  shutdown(): void {
    for (const interval of this.intervals.values()) {
      clearInterval(interval);
    }
  }
}
Kernpunkte
Fehlertoleranz ist eine Designentscheidung, kein Deployment-Problem. Circuit Breaker verhindern kaskadierende Fehler, indem sie Aufrufe an ungesunde Services kurzschließen. Bulkheads isolieren den Ressourcenverbrauch, sodass eine ausgefallene Abhängigkeit die Ressourcen anderer nicht ausschöpfen kann. Fallback-Ketten liefern schrittweise einfachere Antworten, wenn Primärquellen nicht verfügbar sind.
Ordne deine Features nach geschäftlicher Kritikalität und definiere akzeptable abgestufte Zustände für jedes. Das Ziel ist nicht perfekte Verfügbarkeit für jedes Feature, sondern sicherzustellen, dass kritische Pfade funktionieren, auch wenn unterstützende Services ausfallen. Ein System, das Bestellungen auch mit degradierten Empfehlungen weiterverarbeitet, ist unendlich wertvoller als eines, das komplett dunkelgeht, weil die Empfehlungsengine in ein Timeout gelaufen ist.