Backend
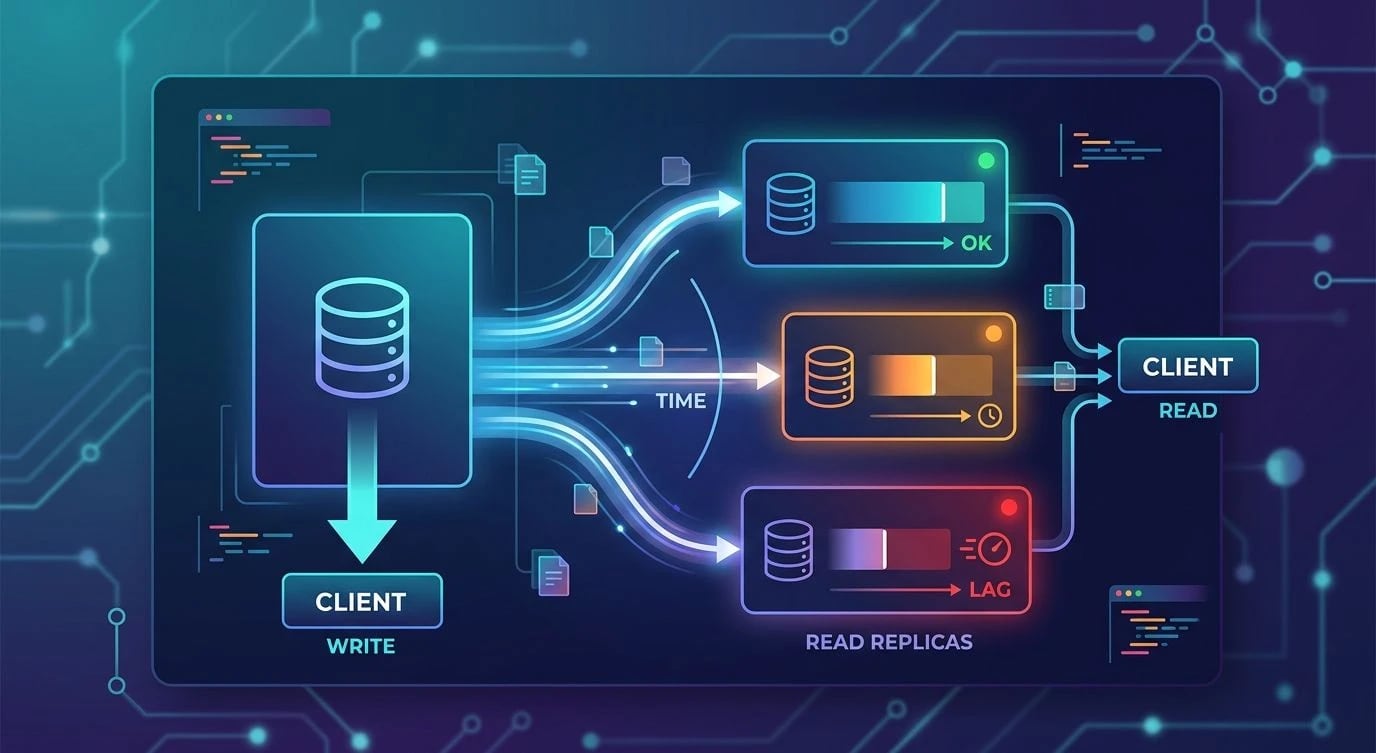
Replication Lag: The Hidden Cost of Read Replicas
Why read replicas introduce stale reads, how replication lag breaks consistency assumptions, and practical patterns to handle it safely.
·4 min read
Tags
20 articles · Page 1 of 2
Why read replicas introduce stale reads, how replication lag breaks consistency assumptions, and practical patterns to handle it safely.
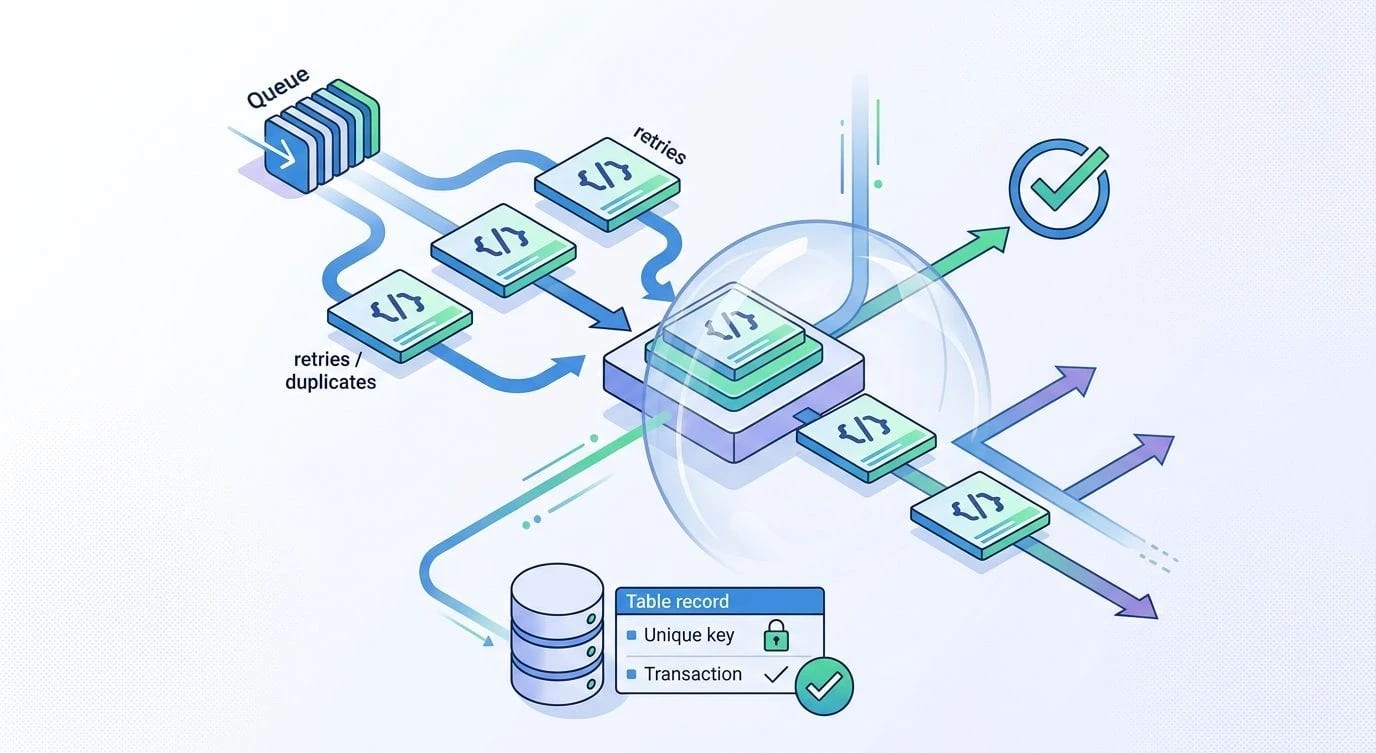
Exactly-once processing does not exist in distributed systems — here is how to design background jobs that survive retries, crashes and duplicate deliveries.
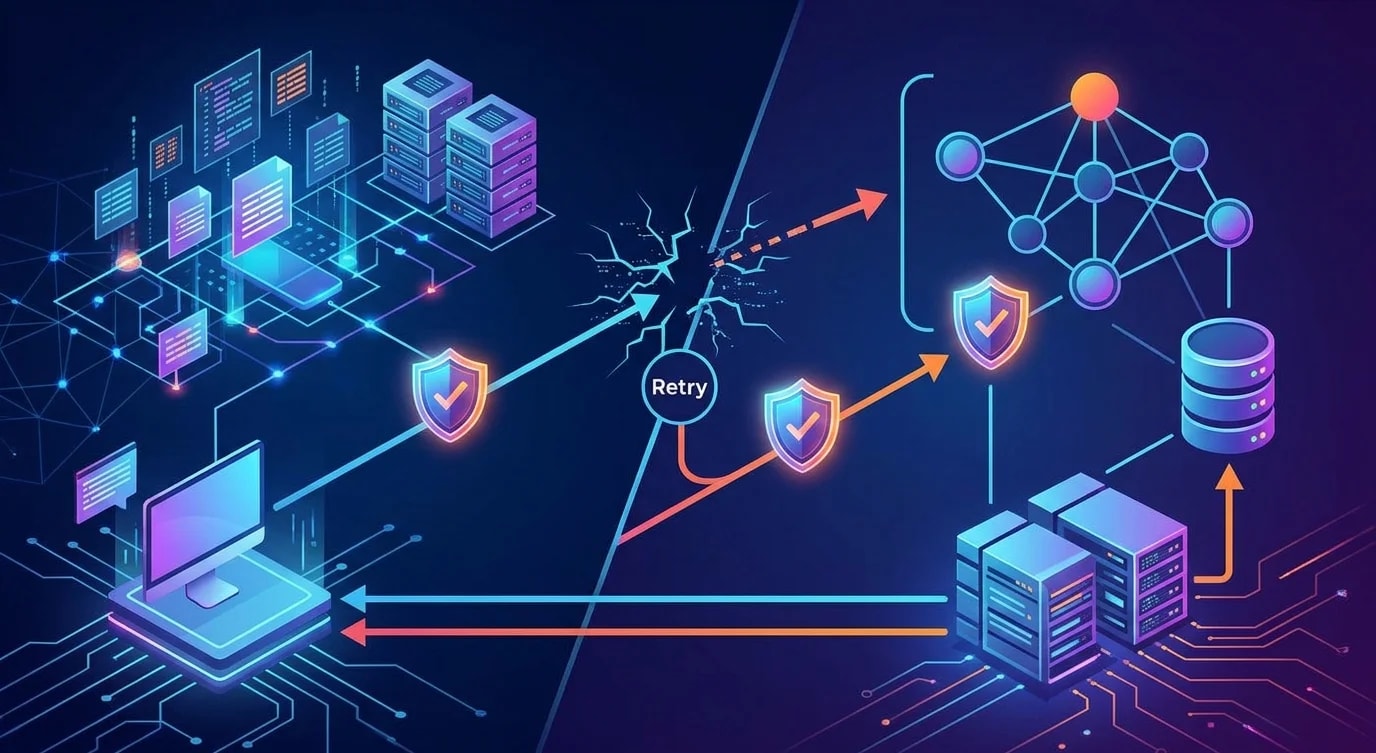
How to design and implement idempotency keys so retried requests never double-charge, double-send, or double-create resources.
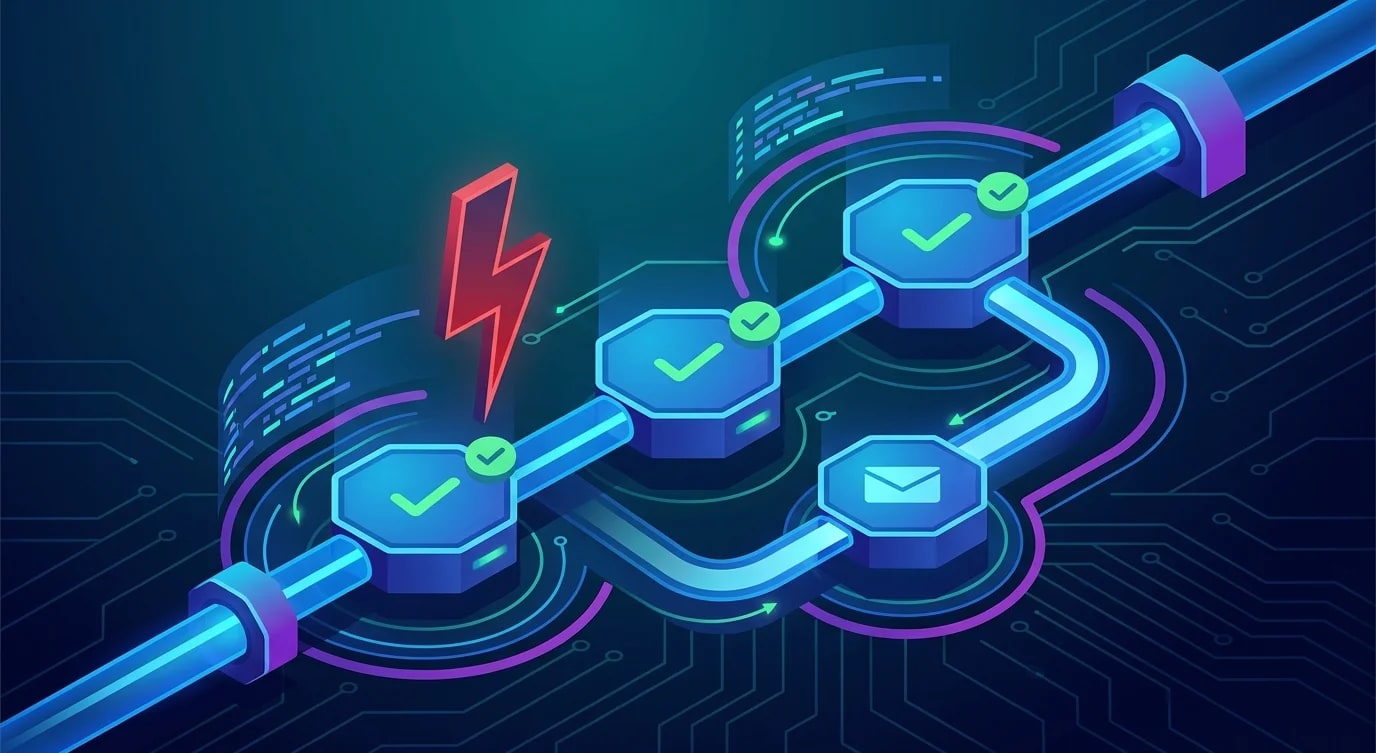
Why job queues and database state machines break on complex multi-step processes, and how durable execution with Temporal survives crashes and deployments.

How the transactional outbox pattern eliminates the dual-write problem and guarantees reliable event publishing without coupling database to broker.
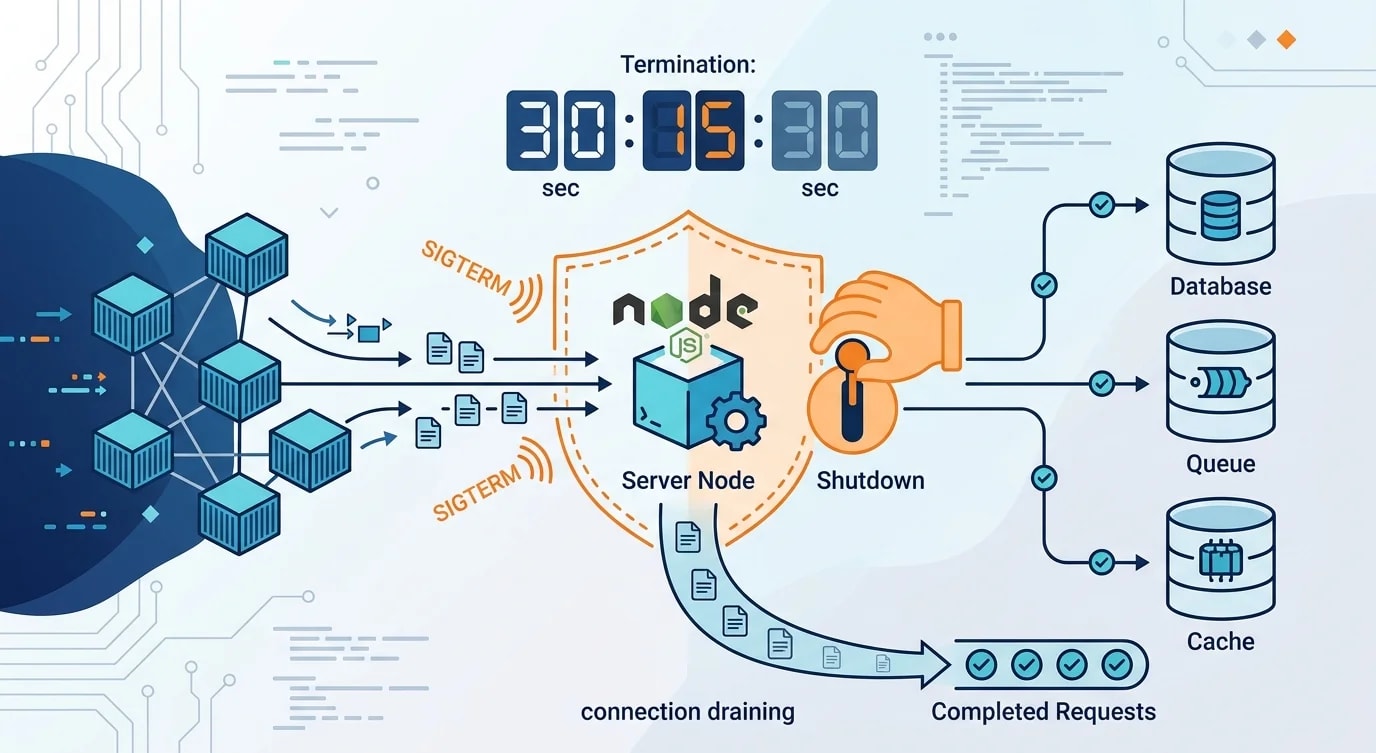
Most Node.js services silently drop in-flight requests on every deploy. How to handle SIGTERM correctly, drain connections and exit cleanly in Kubernetes.
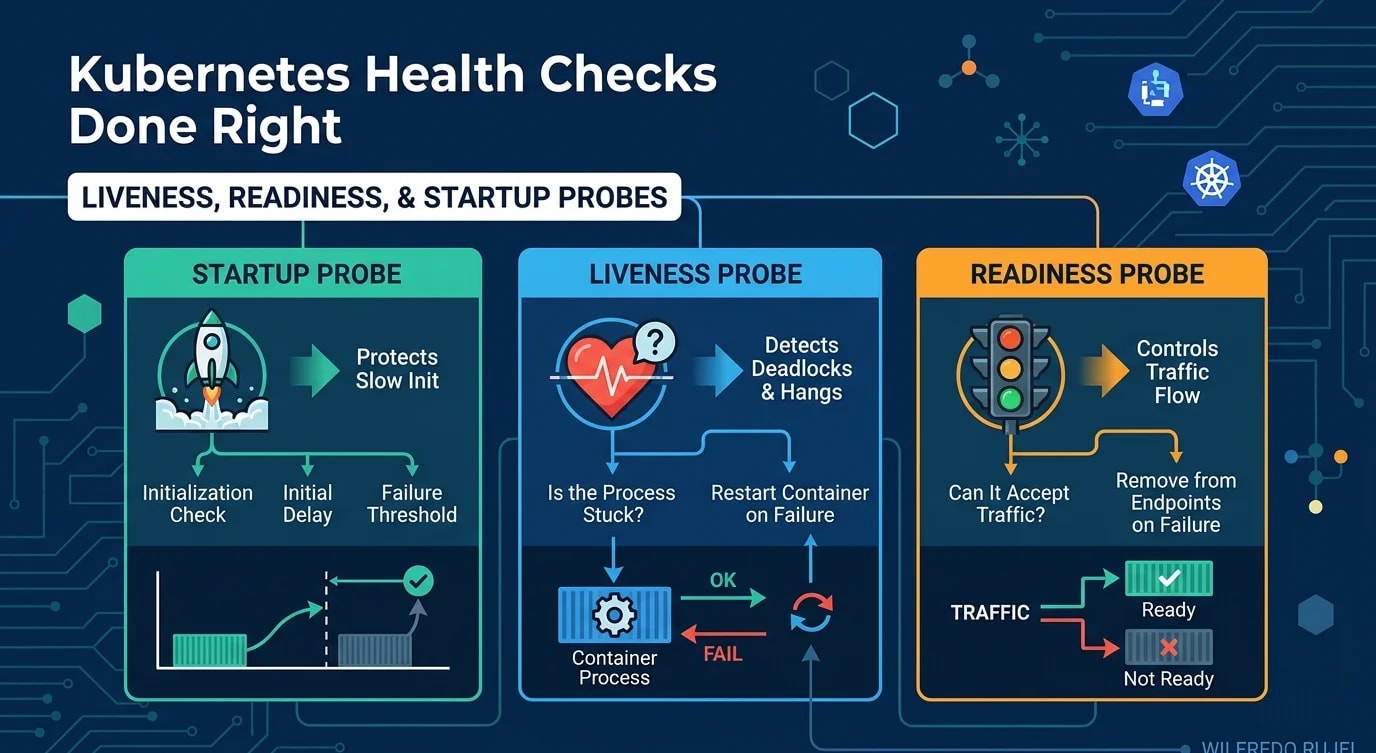
Configure Kubernetes liveness, readiness and startup probes correctly to prevent cascading failures, avoid restart loops and route traffic only when ready.

Practical testing for distributed architectures: contract testing between services, chaos engineering, integration design, and confidence without full E2E.
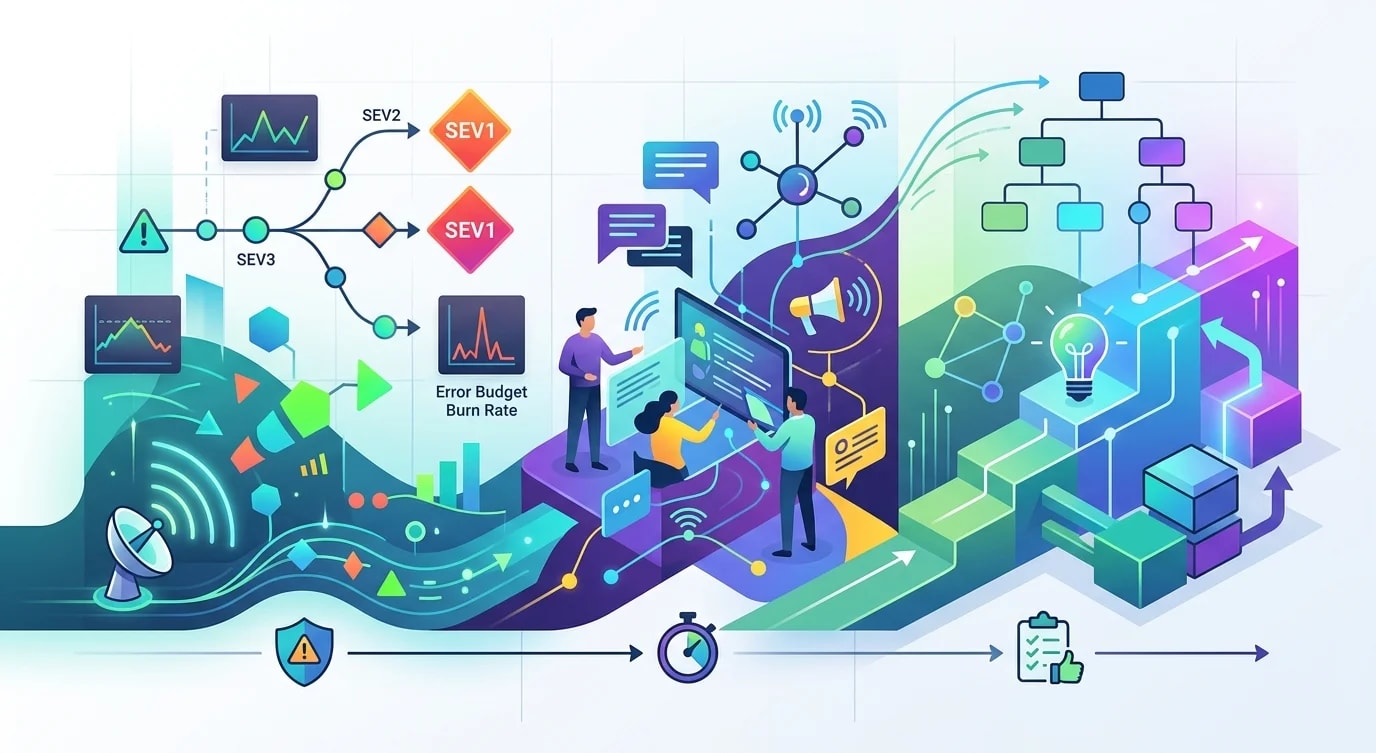
A systematic approach to incident management: alerting design, severity classification, on-call workflows, communication protocols and blameless post-mortems.
Fault tolerance engineering in practice: circuit breakers, bulkheads, fallback chains and degradation strategies that keep systems useful when parts fail.
Practice chaos engineering by injecting controlled failures into production to find weaknesses first: network partitions, resource exhaustion, dependencies.

Build idempotent API endpoints that retry safely using idempotency keys, database constraints and state machines — payments, orders and webhooks.