
Architecture
Designing Resilient Retry Policies for Distributed Systems
Retry policies that recover from transient failures without overwhelming downstream services: exponential backoff, jitter, circuit breakers and budgets.
·4 min read
Tags
8 articles
Retry policies that recover from transient failures without overwhelming downstream services: exponential backoff, jitter, circuit breakers and budgets.
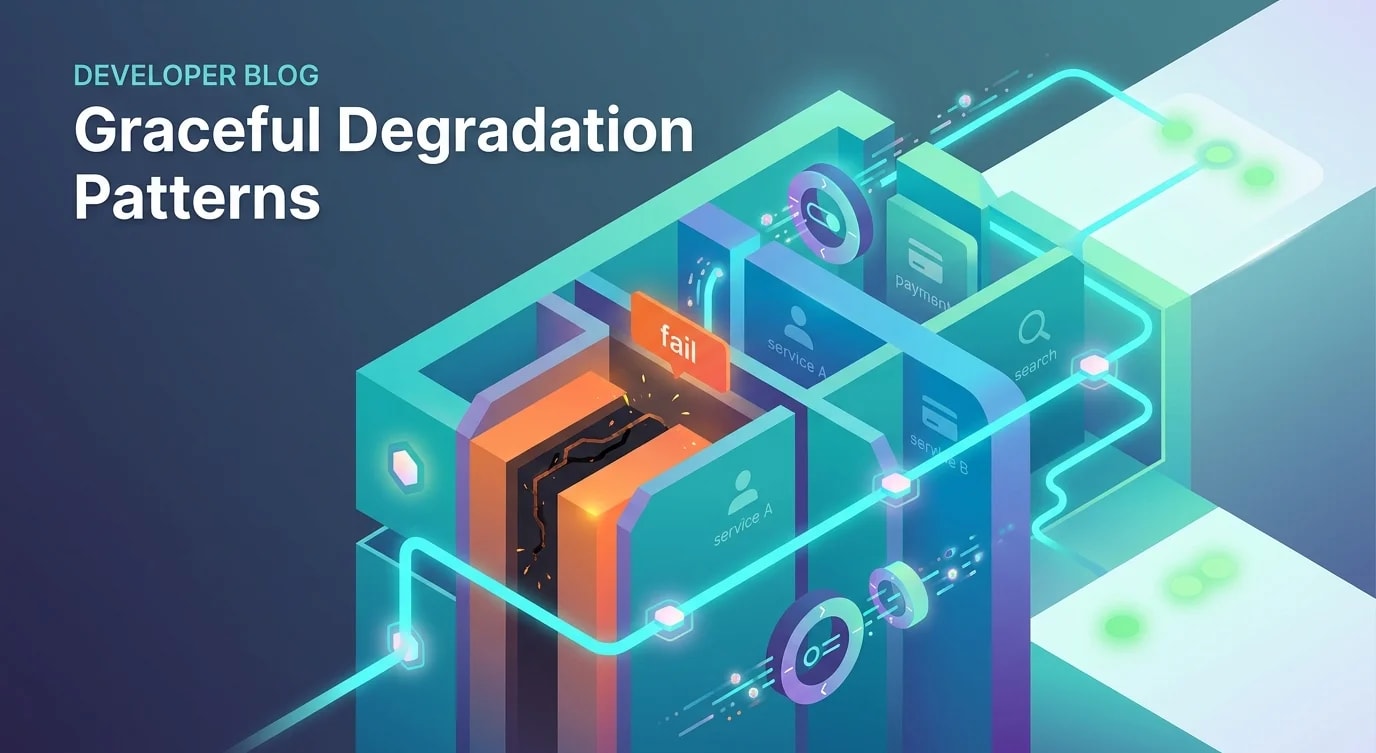
Fault tolerance engineering in practice: circuit breakers, bulkheads, fallback chains and degradation strategies that keep systems useful when parts fail.
Practice chaos engineering by injecting controlled failures into production to find weaknesses first: network partitions, resource exhaustion, dependencies.

Build error boundary strategies that catch failures gracefully, provide meaningful fallbacks, report actionable diagnostics and contain the damage.

Design cell-based architectures that isolate failures to small blast radii, allow independent scaling and stop cascading outages across distributed systems.
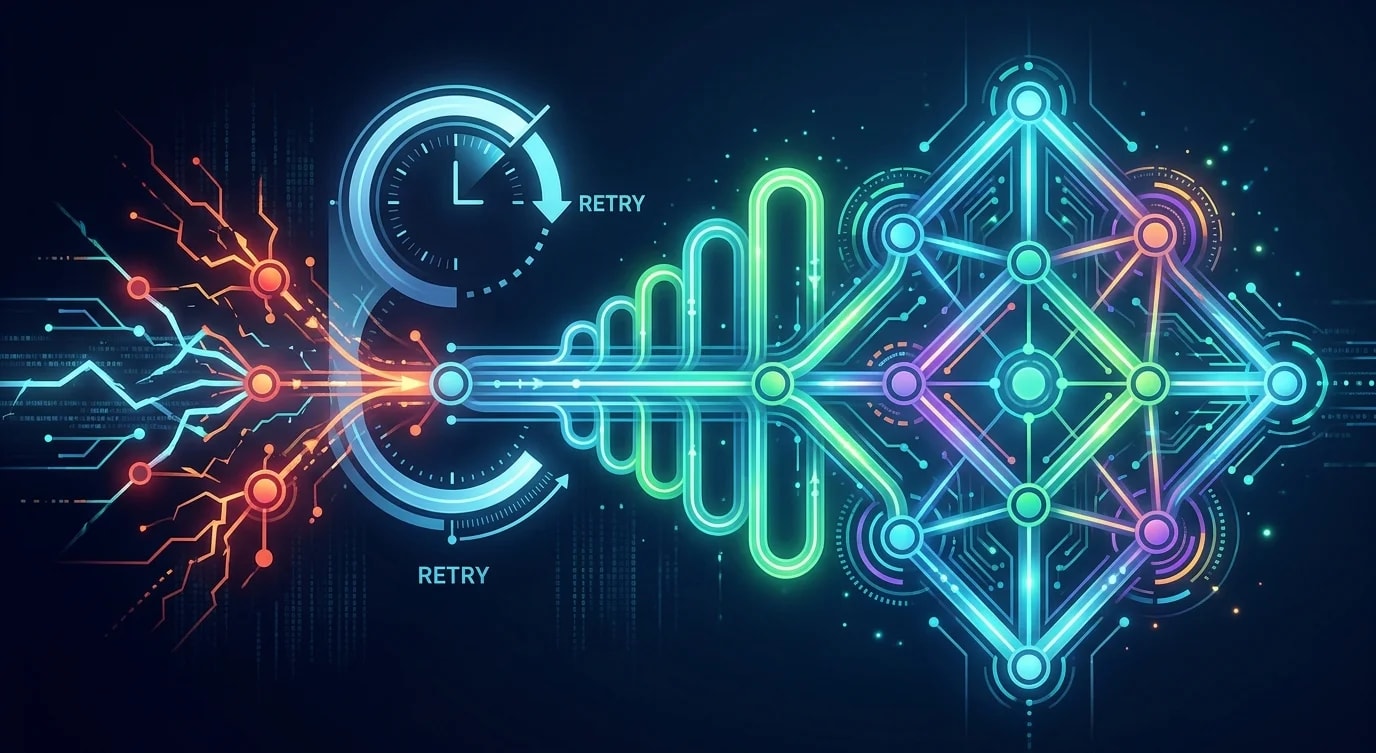
How to implement timeouts, retries, and backoff strategies that prevent cascading failures in distributed architectures.
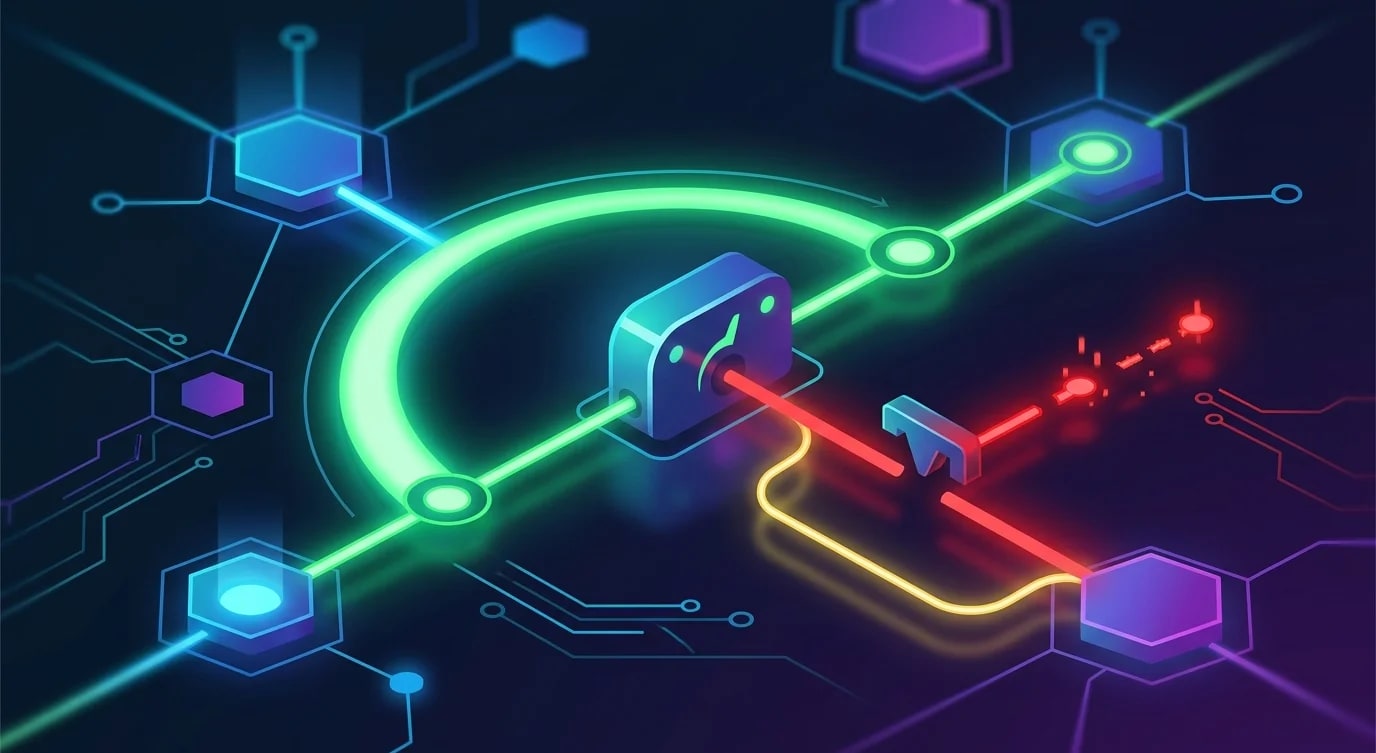
When a downstream service is failing, continuing to send requests makes everything worse — the circuit breaker pattern stops the cascade by failing fast.

Chaos engineering is the practice of deliberately injecting failures into production systems to discover weaknesses before they cause real outages.