
Engineering
Debugging Production Incidents: A Systematic Approach
A battle-tested framework for diagnosing and resolving production incidents quickly — from first alert to root cause analysis and prevention.
·4 min read
Tags
9 articles
A battle-tested framework for diagnosing and resolving production incidents quickly — from first alert to root cause analysis and prevention.

Structured logging in Node.js that produces machine-parsable, searchable entries with correlation IDs, consistent severity levels and context propagation.
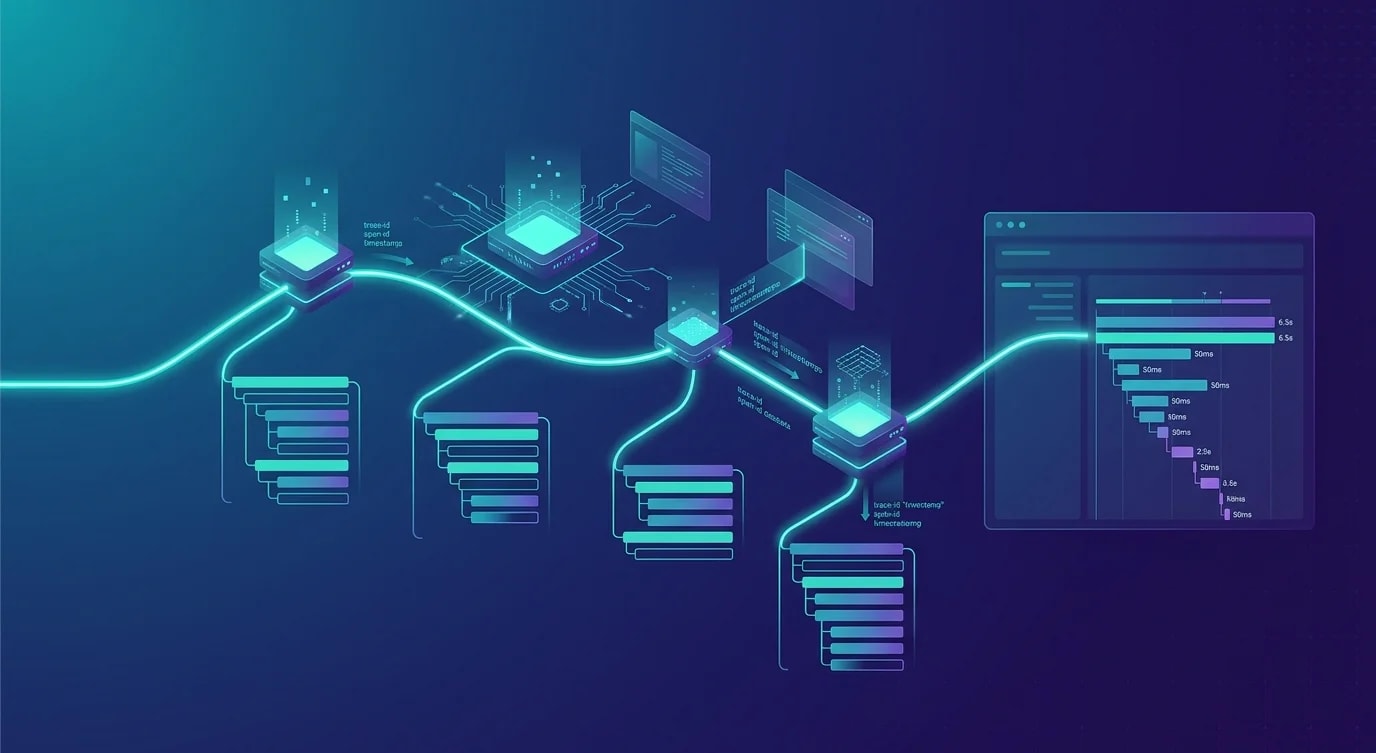
Implement distributed tracing across microservices with OpenTelemetry: context propagation, spans, sampling and the analysis that makes systems debuggable.
Debug distributed systems with correlation IDs, tracing context propagation, log aggregation and causal ordering to follow a request to its root cause.

How to implement structured logging that makes production debugging fast: JSON formats, context propagation, log levels, data masking and aggregation.

Techniques for diagnosing memory leaks, excessive allocation, and OOM kills in production — covering heap snapshots, profiling tools, and common leak patterns.

How to use git bisect, conditional breakpoints, and systematic debugging techniques to find bugs in minutes instead of hours.
When a request touches five services, each log is useless alone — distributed tracing ties them together with trace IDs, spans and context propagation.

Closures, event listeners, and uncleared timers — the most common memory leak patterns in Node.js and how to find them before they crash production.