Prompt Engineering for Code Generation
A practical guide to prompts that produce reliable, production-quality code: structured prompting, few-shot examples, chain-of-thought and evaluation.

Why Most Code Generation Prompts Fail
You type "write a function that validates email addresses" into an LLM and get back code that sort of works. It handles user@domain.com but fails on user+tag@sub.domain.co.uk. The regex is from 2015. There are no tests. The error messages are generic.
The problem is not the model—it is the prompt. Vague prompts produce vague code. The model fills in every detail you leave unspecified with its best guess, and its best guess is an average of everything it has seen in training data. Average code is not production code.
Effective code generation requires treating prompts like specifications. The more precisely you define inputs, outputs, constraints, and edge cases, the more reliable the generated code becomes.
Structured Prompts: The Specification Approach
A structured prompt reads like a technical specification. It defines the function signature, input constraints, expected behavior, edge cases, and quality requirements.
// ❌ Bad prompt: "Write a function to parse CSV files"
// Result: A basic split-by-comma implementation that breaks on quoted fields

// ✅ Good prompt structure:
const structuredPrompt = `
Write a TypeScript function with the following specification:

**Function signature:**
function parseCSV(input: string, options?: CSVOptions): ParsedRow[]

**Types:**
interface CSVOptions {
  delimiter?: string;    // Default: ','
  quote?: string;        // Default: '"'
  header?: boolean;      // Default: true (first row as keys)
  skipEmpty?: boolean;   // Default: true
}

type ParsedRow = Record<string, string> | string[];

**Requirements:**
- Handle quoted fields containing delimiters, newlines, and escaped quotes
- Support custom delimiters (tab, semicolon, pipe)
- When header=true, return Record<string, string>[]
- When header=false, return string[][]
- Throw a descriptive error for malformed CSV (unmatched quotes)
- Handle CRLF, LF, and CR line endings
- Empty lines should be skipped when skipEmpty is true

**Edge cases to handle:**
- Empty input string → return empty array
- Single column CSV
- Trailing delimiter on each line
- UTF-8 characters in values
- Fields that are only whitespace

**Do not use:**
- External libraries (implement from scratch)
- eval() or Function constructor
- Regular expressions for the core parsing (use a state machine)

**Include:** Unit tests using Vitest covering all edge cases listed above.
`;
This prompt eliminates ambiguity. The model cannot make incorrect assumptions about the delimiter handling, the return type conditional, or the line ending normalization because every detail is specified.
Few-Shot Prompting: Teaching by Example
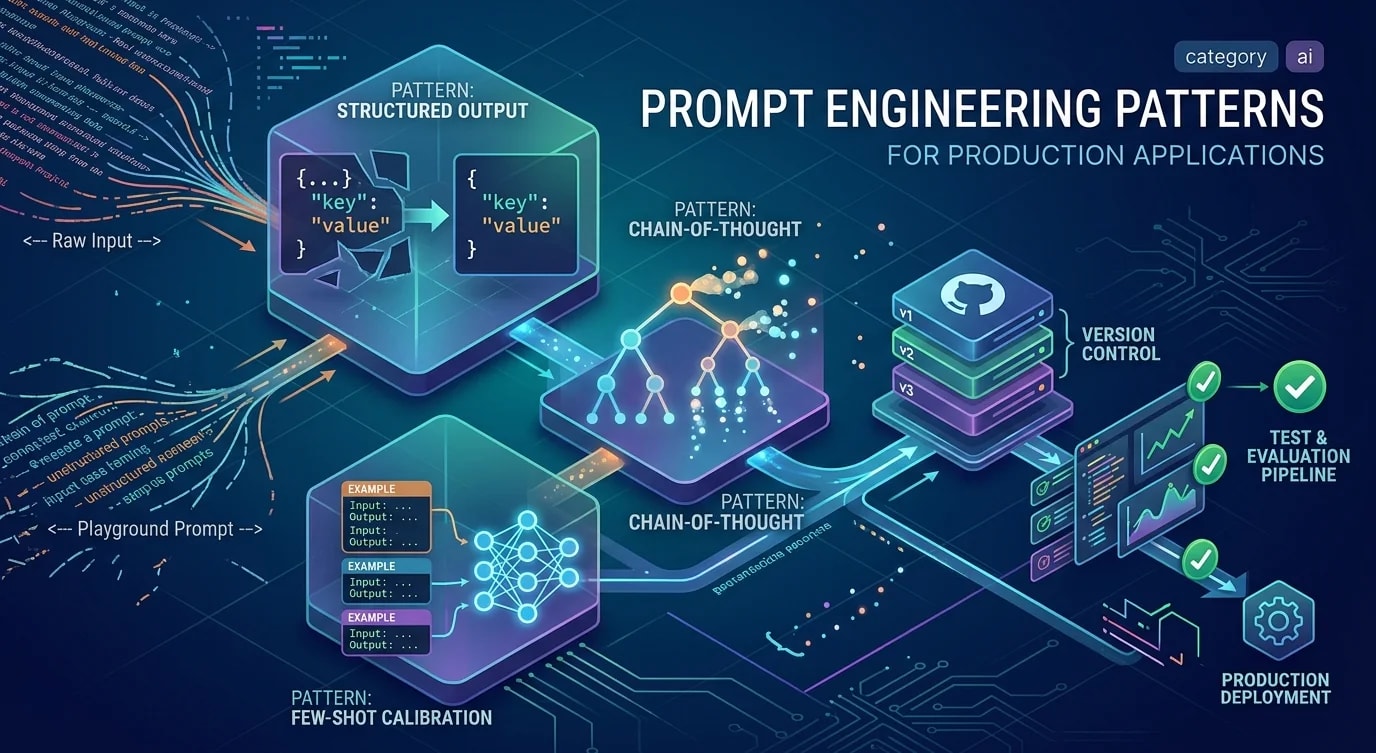
When you need the LLM to follow a specific code style, pattern, or convention, show it examples. Few-shot prompts work better than describing the pattern in words.
// Few-shot prompt for consistent error handling pattern
const fewShotPrompt = `
I need functions that follow this exact error handling pattern:

**Example 1:**
\`\`\`typescript
type Result<T, E = Error> = { ok: true; value: T } | { ok: false; error: E };

async function fetchUser(id: string): Promise<Result<User>> {
  try {
    const response = await db.users.findUnique({ where: { id } });
    if (!response) {
      return { ok: false, error: new Error(\`User \${id} not found\`) };
    }
    return { ok: true, value: response };
  } catch (err) {
    return {
      ok: false,
      error: err instanceof Error ? err : new Error(String(err)),
    };
  }
}
\`\`\`

**Example 2:**
\`\`\`typescript
async function updateEmail(
  userId: string,
  email: string
): Promise<Result<User>> {
  try {
    const validation = validateEmail(email);
    if (!validation.ok) {
      return { ok: false, error: validation.error };
    }
    const updated = await db.users.update({
      where: { id: userId },
      data: { email },
    });
    return { ok: true, value: updated };
  } catch (err) {
    return {
      ok: false,
      error: err instanceof Error ? err : new Error(String(err)),
    };
  }
}
\`\`\`

Now write these functions following the exact same pattern:
1. createProject(name: string, ownerId: string) — creates a project, validates name is 3-50 chars
2. addMember(projectId: string, userId: string, role: "admin" | "member") — adds a member, checks project exists first
3. transferOwnership(projectId: string, currentOwnerId: string, newOwnerId: string) — validates current owner, updates ownership
`;
The two examples establish the Result type convention, the try-catch wrapping pattern, the validation-first flow, and the error coercion pattern. The model will reproduce this style consistently across all three requested functions.
Chain-of-Thought for Complex Logic
For algorithms or complex business logic, asking the model to think through the approach before coding produces significantly better results.
const cotPrompt = `
I need a function that implements a meeting room scheduler.

Before writing code, think through:
1. What data structure best represents room availability?
2. How do you efficiently find the next available slot?
3. How do you handle overlapping booking requests?
4. What's the time complexity of each operation?

Then implement:

\`\`\`typescript
interface MeetingRoom {
  id: string;
  name: string;
  capacity: number;
}

interface BookingRequest {
  roomId: string;
  start: Date;
  end: Date;
  title: string;
  attendees: number;
}

interface Booking extends BookingRequest {
  id: string;
  createdAt: Date;
}

// Implement a MeetingScheduler class with:
// - bookRoom(request: BookingRequest): Booking | null
// - cancelBooking(bookingId: string): boolean
// - findAvailableSlots(date: Date, duration: number, capacity: number): TimeSlot[]
// - getBookingsForRoom(roomId: string, date: Date): Booking[]
\`\`\`

Requirements:
- No double-booking (overlapping times on same room)
- findAvailableSlots should return slots between 8:00-18:00
- Duration is in minutes
- Capacity filter: only show rooms that fit the attendee count
`;
The "think through" section forces the model to plan before implementing. Without it, models often start coding immediately, realize halfway through that their data structure choice was wrong, and produce inconsistent code.
Iterative Refinement: The Conversation Loop
Single-shot code generation rarely produces production-ready results. The most effective workflow treats code generation as a conversation with progressive refinement.
// Round 1: Generate the core implementation
const round1 = "Implement the MeetingScheduler class per the spec above.";

// Round 2: Add error handling
const round2 = `
The implementation works for happy paths. Now add:
- Input validation (start must be before end, duration must be positive)
- Proper error types instead of returning null
- Logging for booking conflicts (which existing booking caused the conflict)
`;

// Round 3: Optimize and test
const round3 = `
Two issues with the current implementation:
1. findAvailableSlots iterates all bookings — this is O(n) per room.
   Refactor to use an interval tree or sorted array with binary search.
2. Add Vitest tests that cover:
   - Booking a room successfully
   - Rejecting overlapping bookings
   - Finding slots across multiple rooms
   - Edge case: booking that starts exactly when another ends
`;

// Round 4: Production hardening
const round4 = `
Final refinements:
- Make the scheduler thread-safe (assume concurrent booking requests)
- Add a cleanup method that removes expired bookings
- Export types for consumers of this module
`;
Each round addresses a specific concern. This is more effective than cramming everything into one prompt because the model can focus its attention on a narrower problem at each step.
Anti-Patterns: Prompts That Produce Bad Code
// ❌ Anti-pattern 1: "Make it work" without constraints
const badPrompt1 = "Write a user authentication system";
// Result: A 200-line monolith with hardcoded passwords

// ❌ Anti-pattern 2: Over-constraining implementation details
const badPrompt2 = `
Write a sort function.
Use a for loop from i=0 to arr.length-1.
Inside that, use another for loop from j=0 to arr.length-i-1.
If arr[j] > arr[j+1], swap them.
`;
// This is just dictating bubble sort — you didn't need an LLM

// ❌ Anti-pattern 3: Asking for everything at once
const badPrompt3 = `
Build a complete REST API with:
- User authentication with JWT, OAuth, and magic links
- CRUD for projects, tasks, comments, and files
- Real-time notifications via WebSocket
- Rate limiting, caching, logging, and monitoring
- Database migrations and seed data
- Docker setup and CI/CD pipeline
- Full test suite with 90% coverage
`;
// Too broad — output will be shallow across everything

// ✅ Better: Focused, one concern at a time
const goodPrompt = `
Write the authentication middleware for a Next.js API.
It should:
- Extract JWT from the Authorization header (Bearer token)
- Verify the token using the HS256 algorithm
- Attach the decoded user to the request context
- Return 401 for missing/invalid tokens with a JSON error body
- Use jose library for JWT verification

Do not implement the login endpoint or token generation — only the middleware.
`;
The best prompts are narrow in scope but rich in detail. They tell the model exactly what to build, exactly what not to build, and exactly how the output should look.
Evaluating Generated Code
Never ship generated code without review. Build a mental checklist for evaluating LLM output.
interface CodeReviewChecklist {
  category: string;
  checks: string[];
}

const llmCodeReview: CodeReviewChecklist[] = [
  {
    category: "Correctness",
    checks: [
      "Does it handle the specified edge cases?",
      "Are there off-by-one errors in loops or slicing?",
      "Does it handle null/undefined inputs?",
      "Are async operations properly awaited?",
    ],
  },
  {
    category: "Security",
    checks: [
      "Any hardcoded secrets or credentials?",
      "Is user input sanitized before use?",
      "Are SQL queries parameterized?",
      "Does it use eval(), innerHTML, or Function()?",
    ],
  },
  {
    category: "Hallucination",
    checks: [
      "Do the imported modules actually exist?",
      "Are the API signatures correct for the library version?",
      "Do referenced config options exist in the framework?",
      "Is the described behavior accurate for the platform?",
    ],
  },
  {
    category: "Production readiness",
    checks: [
      "Error handling for all failure modes?",
      "Appropriate logging without sensitive data?",
      "Resource cleanup (connections, file handles)?",
      "Performance reasonable for expected scale?",
    ],
  },
];
The hallucination category is LLM-specific. Models confidently use API signatures that do not exist, reference configuration options from different framework versions, and invent library functions. Always verify imports and API calls against documentation.
Key Takeaways
Code generation from LLMs is a collaboration, not a command. The quality of the output is bounded by the precision of the input. Treat prompts like technical specifications: define the interface, enumerate edge cases, specify constraints, and show the patterns you want followed.
Use few-shot examples for style consistency, chain-of-thought for complex logic, and iterative refinement for production-quality results. Never ship generated code without checking for hallucinated APIs, security vulnerabilities, and missing edge cases.
The engineers who get the most value from AI code generation are not the ones who write the shortest prompts. They are the ones who invest the most thought into what they ask for, because they understand that a well-specified prompt is already half the implementation.