Load Testing: Finding Breaking Points Before Users Do
Design and run load tests with k6: ramping strategies, realistic user simulation, threshold-based pass/fail criteria and reading results to find bottlenecks.
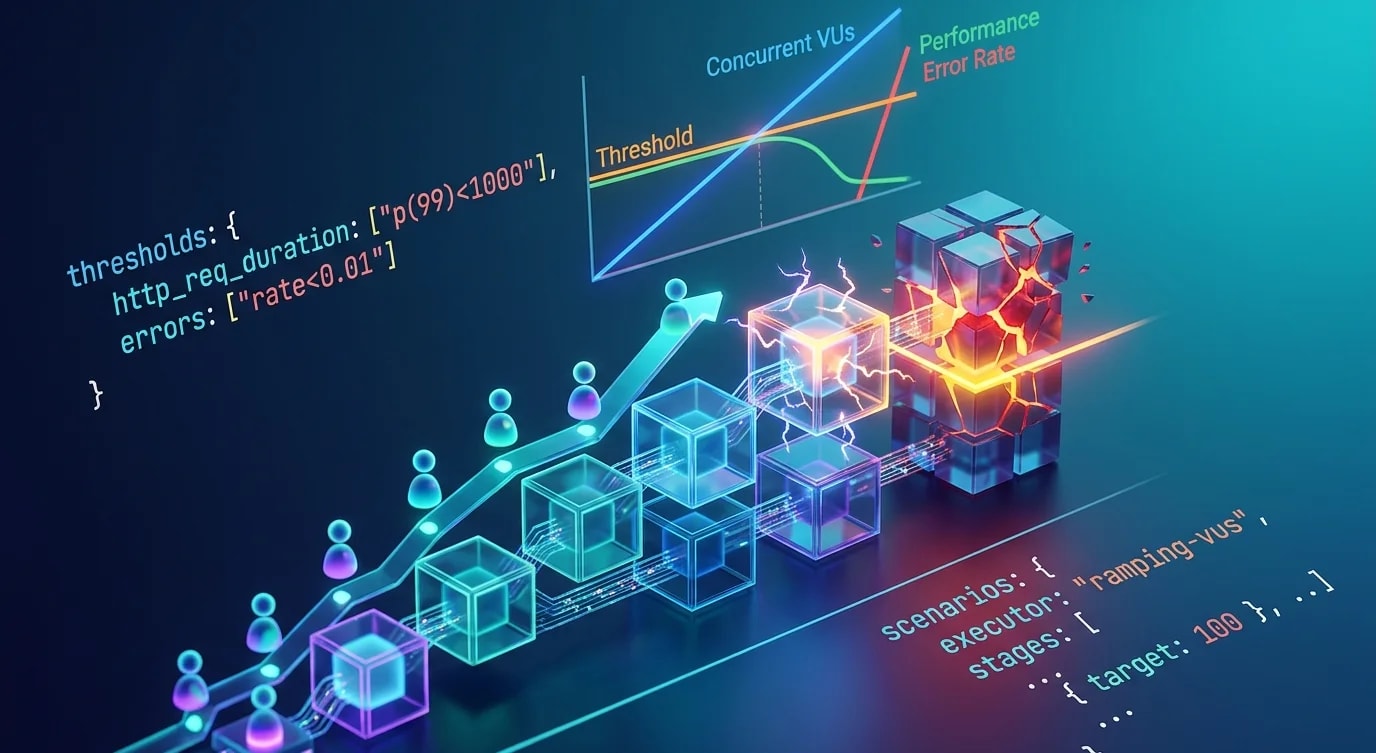
Load testing isn't about proving your system is fast—it's about finding where it breaks. Every system has a capacity ceiling, and discovering that ceiling during a planned test is infinitely better than discovering it when a blog post hits the front page of a social site and real users experience timeouts.
The goal is to answer specific questions: How many concurrent users can we handle before p99 latency exceeds our SLO? Which component fails first under load? What does degradation look like—is it graceful or catastrophic?
Starting with Realistic Scenarios
Load tests that hammer a single endpoint with no think time don't represent real user behavior. Real users browse, pause, click, wait for results, and move to the next page.
// ❌ Unrealistic: hammering one endpoint
import http from "k6/http";

export default function () {
  http.get("https://api.example.com/products");
  // No think time, no user flow, no variety
  // This tests connection handling, not application behavior
}// ✅ Realistic: simulating user behavior
import http from "k6/http";
import { sleep, check } from "k6";
import { Rate, Trend } from "k6/metrics";
const errorRate = new Rate("errors");
const searchLatency = new Trend("search_latency");
const BASE_URL = __ENV.BASE_URL || "https://api.example.com";
export const options = {
scenarios: {
browsing_users: {
executor: "ramping-vus",
startVUs: 0,
stages: [
{ duration: "2m", target: 50 }, // Ramp up
{ duration: "5m", target: 50 }, // Steady state
{ duration: "2m", target: 100 }, // Push higher
{ duration: "5m", target: 100 }, // Sustained load
{ duration: "2m", target: 0 }, // Ramp down
],
},
},
thresholds: {
http_req_duration: ["p(95)<500", "p(99)<1000"],
errors: ["rate<0.01"],
search_latency: ["p(95)<800"],
},
};
export default function () {
// Step 1: Browse homepage
const homeRes = http.get(`${BASE_URL}/`);
check(homeRes, {
"homepage status 200": (r) => r.status === 200,
});
sleep(Math.random() * 3 + 1); // 1-4s think time
// Step 2: Search for a product
const query = ["laptop", "phone", "headset", "monitor"][
Math.floor(Math.random() * 4)
];
const searchStart = Date.now();
const searchRes = http.get(
`${BASE_URL}/api/products/search?q=${query}`
);
searchLatency.add(Date.now() - searchStart);
check(searchRes, {
"search status 200": (r) => r.status === 200,
"search has results": (r) =>
JSON.parse(r.body).length > 0,
});
errorRate.add(searchRes.status !== 200);
sleep(Math.random() * 2 + 1);
// Step 3: View a product detail
const products = JSON.parse(searchRes.body);
if (products.length > 0) {
const product =
products[Math.floor(Math.random() * products.length)];
const detailRes = http.get(
`${BASE_URL}/api/products/${product.id}`
);
check(detailRes, {
"product detail 200": (r) => r.status === 200,
});
errorRate.add(detailRes.status !== 200);
sleep(Math.random() * 5 + 2); // Longer reading time
}
// Step 4: Maybe add to cart (30% of users)
if (Math.random() < 0.3 && products.length > 0) {
const product =
products[Math.floor(Math.random() * products.length)];
const cartRes = http.post(
`${BASE_URL}/api/cart`,
JSON.stringify({
productId: product.id,
quantity: 1,
}),
{ headers: { "Content-Type": "application/json" } }
);
check(cartRes, {
"add to cart 201": (r) => r.status === 201,
});
errorRate.add(cartRes.status !== 201);
}
}Ramping Strategies: Finding the Ceiling
Different ramping strategies answer different questions. Ramp-up tests find the breaking point. Soak tests find memory leaks. Spike tests reveal how the system handles sudden traffic surges.
// Breaking point test: find where performance degrades
export const options = {
  scenarios: {
    breaking_point: {
      executor: "ramping-arrival-rate",
      startRate: 10,
      timeUnit: "1s",
      preAllocatedVUs: 500,
      maxVUs: 1000,
      stages: [
        { duration: "2m", target: 10 },   // Baseline
        { duration: "2m", target: 50 },   // Moderate
        { duration: "2m", target: 100 },  // Heavy
        { duration: "2m", target: 200 },  // Stress
        { duration: "2m", target: 500 },  // Breaking point?
        { duration: "3m", target: 500 },  // Sustain at peak
        { duration: "2m", target: 0 },    // Recovery
      ],
    },
  },
  thresholds: {
    http_req_duration: ["p(95)<2000"],
    http_req_failed: ["rate<0.05"],
  },
};// Soak test: find memory leaks and degradation over time
export const options = {
scenarios: {
soak: {
executor: "constant-arrival-rate",
rate: 50,
timeUnit: "1s",
duration: "2h",
preAllocatedVUs: 100,
maxVUs: 200,
},
},
thresholds: {
http_req_duration: [
"p(95)<500",
// Ensure latency doesn't degrade over time
{
threshold: "p(99)<1500",
abortOnFail: true,
delayAbortEval: "10m",
},
],
},
};// Spike test: sudden traffic surge
export const options = {
scenarios: {
spike: {
executor: "ramping-vus",
startVUs: 0,
stages: [
{ duration: "1m", target: 20 }, // Normal load
{ duration: "10s", target: 500 }, // Spike!
{ duration: "3m", target: 500 }, // Sustained spike
{ duration: "10s", target: 20 }, // Drop back
{ duration: "3m", target: 20 }, // Recovery period
],
},
},
};Threshold-Based Pass/Fail Criteria
Thresholds turn load tests from observational exercises into automated quality gates. Define what "acceptable" means before running the test.
export const options = {
  thresholds: {
    // Global HTTP metrics
    http_req_duration: [
      "p(50)<200",    // Median under 200ms
      "p(95)<500",    // 95th percentile under 500ms
      "p(99)<1000",   // 99th percentile under 1s
      "max<5000",     // No request over 5s
    ],

    // Error rate
    http_req_failed: [
      "rate<0.01",    // Less than 1% error rate
    ],

    // Custom metrics per endpoint
    "http_req_duration{name:search}": [
      "p(95)<800",    // Search specifically under 800ms
    ],
    "http_req_duration{name:checkout}": [
      "p(95)<2000",   // Checkout allowed longer
    ],

    // Custom business metrics
    errors: ["rate<0.005"],  // Custom error tracking

    // Abort conditions — stop early if critically broken
    http_req_duration: [
      {
        threshold: "p(99)<3000",
        abortOnFail: true,
        delayAbortEval: "30s",
      },
    ],
  },
};

// Tag requests for per-endpoint thresholds
export default function () {
  http.get(`${BASE_URL}/api/search?q=test`, {
    tags: { name: "search" },
  });

  http.post(`${BASE_URL}/api/checkout`, body, {
    tags: { name: "checkout" },
  });
}
Interpreting Results: Finding Bottlenecks
Raw throughput numbers are meaningless without understanding what's limiting performance. Look for inflection points where latency spikes.
## What to look for in results:

### Healthy system pattern:
  Throughput ─────────────────────────────────
  Latency   ────────────────────── (flat, low)
  Errors    ─── (near zero)

### Database bottleneck pattern:
  Throughput ───────────────┐ (plateaus)
  Latency               ╱ (exponential rise)
  Connection pool       ╱  (waiting > 0)
  DB CPU                █████████ (saturated)

### Memory leak pattern:
  Throughput ──────────────── (stable initially)
  Memory     ╱╱╱╱╱╱╱╱╱╱╱╱╱╱ (steady climb)
  Then:
  Throughput ────────┐ (sudden drop)
  Latency          ╱╱╱╱ (spikes, GC pauses)
  Errors         ╱╱╱╱╱╱ (OOM errors)

### Connection pool exhaustion:
  Active connections  ████ (at max)
  Waiting queries     ▊▊▊▊▊▊▊ (growing queue)
Latency p99 ╱╱╱╱╱ (timeout-shaped)// Include system metrics in your test for correlation
import http from "k6/http";
import { Trend, Counter } from "k6/metrics";
const dbQueryTime = new Trend("db_query_time");
const cacheHits = new Counter("cache_hits");
const cacheMisses = new Counter("cache_misses");
export default function () {
const res = http.get(`${BASE_URL}/api/products`);
// Extract server-side metrics from response headers
const serverTiming = res.headers["Server-Timing"];
if (serverTiming) {
const dbMatch = serverTiming.match(
/db;dur=([\d.]+)/
);
if (dbMatch) {
dbQueryTime.add(parseFloat(dbMatch[1]));
}
}
// Track cache effectiveness via headers
const cacheStatus = res.headers["X-Cache-Status"];
if (cacheStatus === "HIT") {
cacheHits.add(1);
} else {
cacheMisses.add(1);
}
}CI Integration
Load tests in CI prevent performance regressions from reaching production. Run them against a staging environment that mirrors production infrastructure.
# .github/workflows/load-test.yml
name: Load Test

on:
  pull_request:
    branches: [main]
  schedule:
    - cron: "0 6 * * 1" # Weekly Monday 6am

jobs:
  load-test:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4

      - name: Install k6
        run: |
          sudo gpg -k
          sudo gpg --no-default-keyring --keyring /usr/share/keyrings/k6-archive-keyring.gpg \
            --keyserver hkp://keyserver.ubuntu.com:80 --recv-keys C5AD17C747E3415A3642D57D77C6C491D6AC1D68
          echo "deb [signed-by=/usr/share/keyrings/k6-archive-keyring.gpg] https://dl.k6.io/deb stable main" \
            | sudo tee /etc/apt/sources.list.d/k6.list
          sudo apt-get update && sudo apt-get install k6

      - name: Run load test
        run: |
          k6 run \
            --env BASE_URL=${{ secrets.STAGING_URL }} \
            --out json=results.json \
            tests/load/user-flow.js

      - name: Upload results
        if: always()
        uses: actions/upload-artifact@v4
        with:
          name: load-test-results
          path: results.json
Key Takeaways
Simulate realistic user behavior with varied endpoints, think time between actions, and probabilistic paths through the application—tests that hammer a single endpoint with zero delay measure connection handling, not application performance under real conditions. Use different ramping strategies for different questions: ramp-up tests find the breaking point, soak tests find memory leaks and degradation over time, and spike tests reveal how gracefully the system handles sudden traffic surges. Define thresholds as automated pass/fail criteria before running tests—p95 latency, error rates, and per-endpoint targets turn load tests from observational exercises into quality gates that catch regressions in CI. Look for inflection points in results rather than raw throughput numbers—a latency spike that correlates with connection pool exhaustion, CPU saturation, or memory pressure tells you exactly which component to optimize, while a throughput plateau without latency growth indicates a well-designed backpressure mechanism.