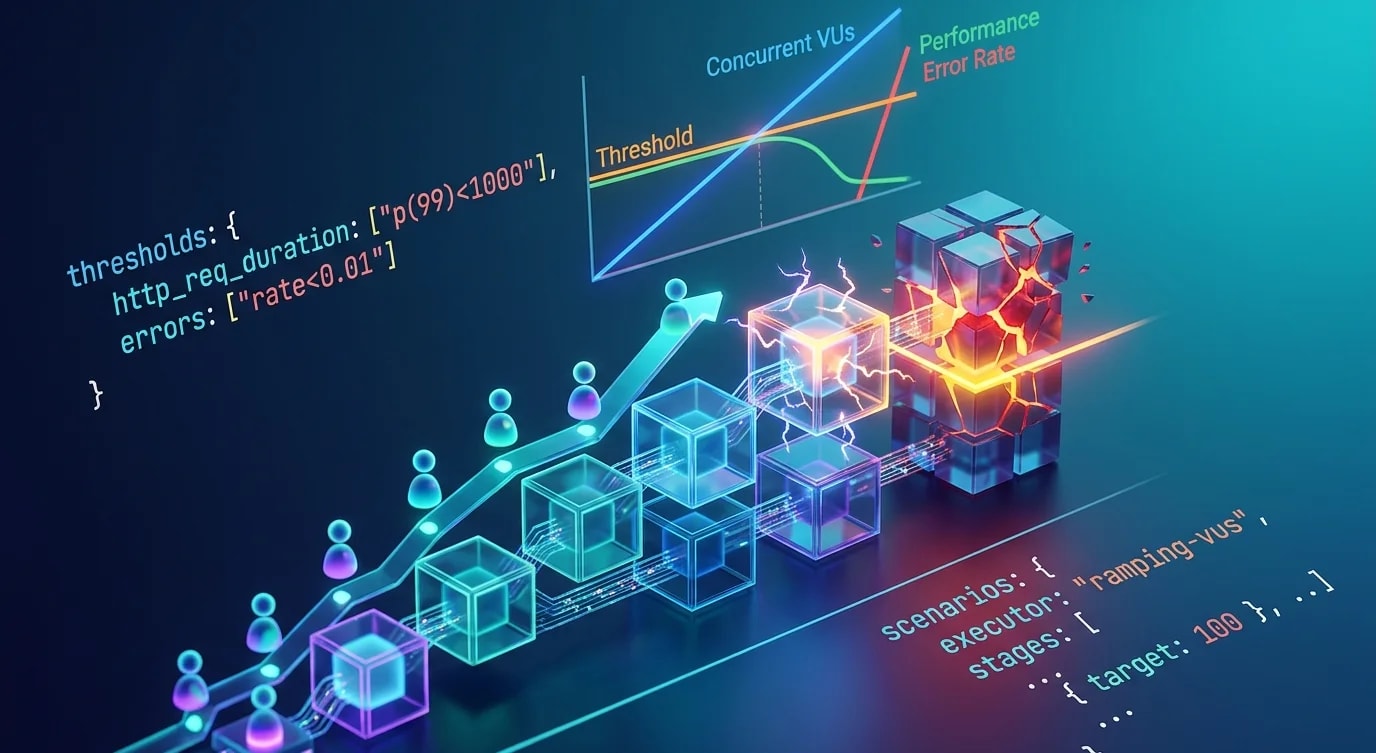
Load Testing Your API: Tools, Patterns, and Pitfalls
A practical guide to load testing APIs: tool selection, realistic traffic patterns, performance baselines, bottleneck identification and common mistakes.

Load testing answers a simple question: what happens when real traffic hits your system? Not theoretical capacity — actual behavior under load. Most performance problems are invisible at low traffic and catastrophic at high traffic. Load testing finds them before your users do.
The challenge is not running a load test. The challenge is designing a test that produces meaningful results. Hammering an endpoint with 10,000 requests per second tells you something, but probably not what you need to know.
Choosing the Right Tool
Different tools suit different needs. The best tool is the one your team will actually use.
// k6 — JavaScript-based, good for developers
// Install: brew install k6
// Run: k6 run loadtest.js

import http from 'k6/http';
import { check, sleep } from 'k6';

export const options = {
  stages: [
    { duration: '2m', target: 50 },   // Ramp up to 50 users
    { duration: '5m', target: 50 },   // Stay at 50 users
    { duration: '2m', target: 200 },  // Ramp up to 200 users
    { duration: '5m', target: 200 },  // Stay at 200 users
    { duration: '2m', target: 0 },    // Ramp down
  ],
  thresholds: {
    http_req_duration: ['p(95)<500'],  // 95% of requests under 500ms
    http_req_failed: ['rate<0.01'],    // Less than 1% error rate
  },
};

export default function () {
  const res = http.get('https://api.example.com/products');

  check(res, {
    'status is 200': (r) => r.status === 200,
    'response time < 500ms': (r) => r.timings.duration < 500,
    'has products': (r) => JSON.parse(r.body).length > 0,
  });

  sleep(1); // Simulate user think time
}
Key difference from other tools: k6 scripts are real JavaScript. You can use variables, loops, conditionals, and shared state. Tests read like application code, not XML configuration.
Realistic Traffic Patterns
The biggest load testing mistake: sending uniform traffic to a single endpoint.
// ❌ Unrealistic — all requests hit the same endpoint at the same rate
export default function () {
  http.get('https://api.example.com/products');
}
// Real users don't do this. Your cache warms up for one endpoint
// while the rest of the system is untested.// ✅ Realistic — model actual user behavior
import http from 'k6/http';
import { sleep, group } from 'k6';
const BASE_URL = 'https://api.example.com';
export default function () {
// 60% of traffic: browse products
group('browse', () => {
http.get(`${BASE_URL}/products`);
sleep(2);
const productId = Math.floor(Math.random() * 1000) + 1;
http.get(`${BASE_URL}/products/${productId}`);
sleep(3);
});
// 25% of traffic: search
if (Math.random() < 0.25) {
group('search', () => {
const queries = ['laptop', 'headphones', 'keyboard', 'monitor', 'mouse'];
const query = queries[Math.floor(Math.random() * queries.length)];
http.get(`${BASE_URL}/search?q=${query}`);
sleep(2);
});
}
// 10% of traffic: add to cart and checkout
if (Math.random() < 0.10) {
group('checkout', () => {
const payload = JSON.stringify({
productId: Math.floor(Math.random() * 1000) + 1,
quantity: 1,
});
http.post(`${BASE_URL}/cart`, payload, {
headers: { 'Content-Type': 'application/json' },
});
sleep(1);
http.post(`${BASE_URL}/checkout`, '{}', {
headers: { 'Content-Type': 'application/json' },
});
});
}
// 5% of traffic: authenticated user actions
if (Math.random() < 0.05) {
group('account', () => {
http.get(`${BASE_URL}/account/orders`, {
headers: { 'Authorization': `Bearer ${getTestToken()}` },
});
});
}
}
function getTestToken(): string {
// Use pre-generated test tokens — don't hit the auth endpoint in load tests
const tokens = ['token-1', 'token-2', 'token-3'];
return tokens[Math.floor(Math.random() * tokens.length)];
}The traffic distribution (60% browse, 25% search, 10% checkout, 5% account) should match your production analytics. If 1% of real traffic goes to checkout, testing checkout at 50% load gives meaningless results.
Establishing Baselines
Before load testing, establish single-request baselines. You need to know what "normal" looks like before you can identify "degraded."
// baseline.js — run with: k6 run --vus 1 --iterations 100 baseline.js
import http from 'k6/http';
import { check } from 'k6';
import { Trend } from 'k6/metrics';

const productListDuration = new Trend('product_list_duration');
const productDetailDuration = new Trend('product_detail_duration');
const searchDuration = new Trend('search_duration');
const checkoutDuration = new Trend('checkout_duration');

export default function () {
  // Product list
  let res = http.get('https://api.example.com/products');
  productListDuration.add(res.timings.duration);
  check(res, { 'product list 200': (r) => r.status === 200 });

  // Product detail
  res = http.get('https://api.example.com/products/1');
  productDetailDuration.add(res.timings.duration);
  check(res, { 'product detail 200': (r) => r.status === 200 });

  // Search
  res = http.get('https://api.example.com/search?q=laptop');
  searchDuration.add(res.timings.duration);
  check(res, { 'search 200': (r) => r.status === 200 });
}
## Expected output format:
product_list_duration....: avg=45ms p(95)=78ms p(99)=120ms
product_detail_duration..: avg=12ms p(95)=25ms p(99)=45ms
search_duration..........: avg=95ms p(95)=180ms p(99)=310ms
## Now you know:
## - Product list: baseline P95 is 78ms
## - If load test shows P95 at 400ms, that's 5x degradation
## - Search at 180ms P95 is already slow — investigate before load testing
Identifying Bottlenecks
Load test results point to bottlenecks. The patterns are predictable.
## Bottleneck Patterns

### Latency increases linearly with load
- Cause: CPU-bound processing (no concurrency)
- Fix: Profile the hot path, optimize or parallelize

### Latency is stable until a threshold, then spikes
- Cause: Resource exhaustion (connection pool, thread pool, memory)
- Fix: Increase pool size, add horizontal scaling

### Error rate increases with load
- Cause: Timeout or circuit breaker tripping
- Fix: Increase timeout, add retry with backoff, scale backend

### First request is slow, subsequent are fast
- Cause: Cold cache, JIT compilation, connection establishment
- Fix: Warm caches on deploy, use connection pooling// k6 custom metrics for bottleneck identification
import { Counter, Trend } from 'k6/metrics';
const dbQueryDuration = new Trend('db_query_duration');
const cacheHitRate = new Counter('cache_hits');
const cacheMissRate = new Counter('cache_misses');
export default function () {
const res = http.get('https://api.example.com/products');
// Parse custom headers that expose server timing
const serverTiming = res.headers['Server-Timing'];
if (serverTiming) {
// Server-Timing: db;dur=45, cache;desc="miss"
const dbMatch = serverTiming.match(/db;dur=(\d+)/);
if (dbMatch) {
dbQueryDuration.add(parseInt(dbMatch[1]));
}
if (serverTiming.includes('cache;desc="hit"')) {
cacheHitRate.add(1);
} else {
cacheMissRate.add(1);
}
}
}Expose Server-Timing headers from your API in staging environments. They let you decompose total latency into database time, cache lookups, and application processing without instrumenting the load test client.
Common Mistakes
// ❌ Mistake 1: Testing against production
// Affects real users, skews analytics, risks data corruption

// ❌ Mistake 2: No warm-up period
export const options = {
  vus: 1000,  // Immediate spike — not representative of real traffic
  duration: '30s',
};

// ✅ Always ramp up gradually
export const options = {
  stages: [
    { duration: '5m', target: 100 },
    { duration: '10m', target: 100 },
    { duration: '5m', target: 0 },
  ],
};

// ❌ Mistake 3: Ignoring think time
export default function () {
  http.get(url);  // Fires as fast as possible
  // 50 VUs without sleep = thousands of RPS
  // 50 real users make maybe 1 request per 3 seconds each
}

// ✅ Include realistic think time
export default function () {
  http.get(url);
  sleep(Math.random() * 3 + 1); // 1-4 seconds between actions
}

// ❌ Mistake 4: Only looking at averages
// "Average response time: 200ms" hides that P99 is 8 seconds

// ✅ Always check percentiles
export const options = {
  thresholds: {
    http_req_duration: [
      'p(50)<200',   // Median under 200ms
      'p(95)<500',   // 95th percentile under 500ms
      'p(99)<2000',  // 99th percentile under 2 seconds
    ],
  },
};
Key Takeaways
- Model realistic traffic — match your production traffic distribution, not uniform requests to one endpoint
- Establish baselines first — you need to know "normal" latency before you can detect degradation
- Ramp up gradually — sudden spikes are DDoS simulations, not load tests
- Include think time — real users pause between actions; without sleep, 50 VUs generates unrealistic load
- Check percentiles, not averages — P95 and P99 reveal the experience of your worst-affected users
- Expose server timing —
Server-Timingheaders let you decompose latency without changing the test client