Kubernetes Pods and Deployments: A Practical Introduction
A hands-on guide to Kubernetes Pods, Deployments, and Services — covering the core abstractions you need to run production workloads.
Kubernetes documentation is vast. The API surface is enormous. New engineers stare at a wall of YAML and wonder where to begin. The answer is three primitives: Pods, Deployments, and Services. These three abstractions handle 90% of what you need to run a web application in production.
This guide covers what each primitive does, how they interact, and the configurations that matter for real workloads.
Pods: The Smallest Unit
A Pod is one or more containers running together on the same node, sharing network and storage. Most Pods run a single container. The multi-container pattern is for sidecars — a logging agent, a proxy, or an init container that runs setup before the main process.
# A minimal Pod definition — rarely used directly in production
apiVersion: v1
kind: Pod
metadata:
  name: api-server
  labels:
    app: api
    version: v1
spec:
  containers:
    - name: api
      image: myregistry/api-server:1.4.2
      ports:
        - containerPort: 3000
      env:
        - name: NODE_ENV
          value: "production"
        - name: DATABASE_URL
          valueFrom:
            secretKeyRef:
              name: db-credentials
              key: url
      resources:
        requests:
          memory: "128Mi"
          cpu: "100m"
        limits:
          memory: "256Mi"
          cpu: "500m"
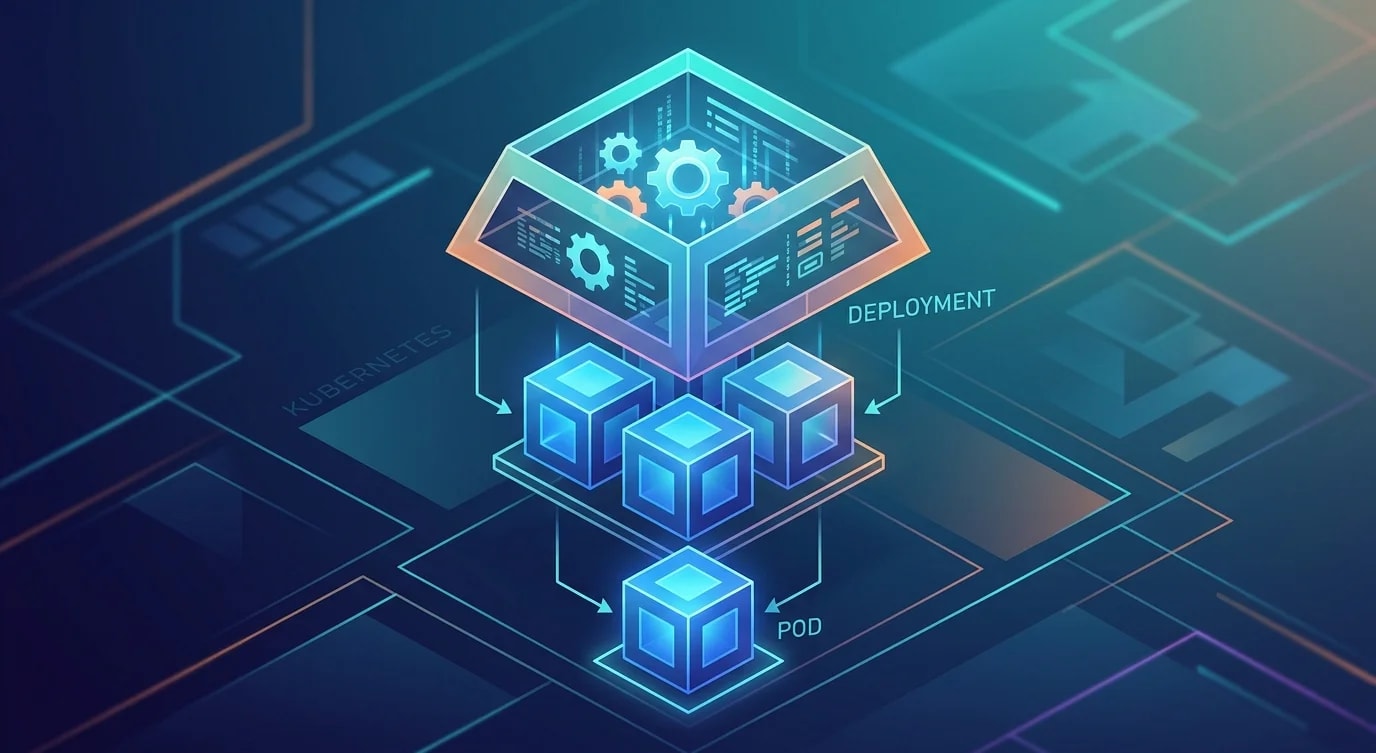
You almost never create Pods directly. If a Pod dies, nothing restarts it. Deployments manage Pod lifecycle, which is why they are the actual unit of work in production.
Deployments: Managing Pod Lifecycle
A Deployment declares the desired state — which container image, how many replicas, and how to roll out updates. The Deployment controller continuously reconciles reality with this desired state.
# ❌ Running pods directly — no restart, no scaling, no rollback
apiVersion: v1
kind: Pod
metadata:
  name: api-server-1
spec:
  containers:
    - name: api
      image: myregistry/api-server:1.4.2
---
apiVersion: v1
kind: Pod
metadata:
  name: api-server-2
spec:
  containers:
    - name: api
image: myregistry/api-server:1.4.2# ✅ A Deployment manages pods with automatic restart, scaling, and rollback
apiVersion: apps/v1
kind: Deployment
metadata:
name: api-server
labels:
app: api
spec:
replicas: 3
selector:
matchLabels:
app: api
strategy:
type: RollingUpdate
rollingUpdate:
maxSurge: 1
maxUnavailable: 0
template:
metadata:
labels:
app: api
version: v1
spec:
containers:
- name: api
image: myregistry/api-server:1.4.2
ports:
- containerPort: 3000
resources:
requests:
memory: "128Mi"
cpu: "100m"
limits:
memory: "256Mi"
cpu: "500m"
readinessProbe:
httpGet:
path: /health
port: 3000
initialDelaySeconds: 5
periodSeconds: 10
livenessProbe:
httpGet:
path: /health
port: 3000
initialDelaySeconds: 15
periodSeconds: 20Key fields in this Deployment:
- replicas: 3 — run three instances of the Pod
- maxSurge: 1 — during updates, allow one extra Pod above the desired count
- maxUnavailable: 0 — never drop below the desired replica count during updates
- readinessProbe — tells Kubernetes when the Pod can accept traffic
- livenessProbe — tells Kubernetes when the Pod is stuck and should be restarted
Rolling Updates and Rollbacks
Deployments manage updates by gradually replacing old Pods with new ones. The maxSurge and maxUnavailable settings control update speed and availability.
# Update the image — triggers a rolling update
kubectl set image deployment/api-server \
  api=myregistry/api-server:1.5.0

# Watch the rollout progress
kubectl rollout status deployment/api-server

# Check rollout history
kubectl rollout history deployment/api-server

# Rollback to the previous version
kubectl rollout undo deployment/api-server

# Rollback to a specific revision
kubectl rollout undo deployment/api-server --to-revision=3
The rolling update process with maxSurge: 1, maxUnavailable: 0 and 3 replicas works like this:
Step 1: [v1] [v1] [v1] [v2]     ← new Pod created (4 total)
Step 2: [v1] [v1] [v2] [v2]     ← old Pod removed, new created
Step 3: [v1] [v2] [v2] [v2]     ← continuing replacement
Step 4: [v2] [v2] [v2]          ← rollout complete (3 total)
Traffic only routes to Pods that pass the readiness probe, so users never hit a Pod that is still starting up.
Services: Exposing Pods
Pods get ephemeral IP addresses that change on restart. A Service provides a stable network identity — a fixed DNS name and IP that routes traffic to healthy Pods matching a label selector.
# ClusterIP Service — internal access only
apiVersion: v1
kind: Service
metadata:
  name: api-service
spec:
  type: ClusterIP
  selector:
    app: api
  ports:
    - protocol: TCP
      port: 80
      targetPort: 3000
---
# Other pods can now reach the API at http://api-service:80
# Kubernetes DNS resolves api-service to the ClusterIP# LoadBalancer Service — external access via cloud load balancer
apiVersion: v1
kind: Service
metadata:
name: api-external
spec:
type: LoadBalancer
selector:
app: api
ports:
- protocol: TCP
port: 443
targetPort: 3000Service types serve different purposes:
- ClusterIP: Internal only. Microservices talking to each other.
- NodePort: Exposes on each node's IP at a static port. Useful for development.
- LoadBalancer: Provisions a cloud load balancer. The standard for public-facing services.
Resource Requests and Limits
Without resource configuration, a single Pod can consume all node resources, starving other workloads. Requests guarantee a minimum allocation. Limits cap the maximum.
resources:
  # Requests: minimum guaranteed resources
  # Used by scheduler to place pods on nodes
  requests:
    memory: "128Mi"
    cpu: "100m"    # 100 millicores = 0.1 CPU cores

  # Limits: maximum allowed resources
  # Pod is killed (OOMKill) if it exceeds memory limit
  # Pod is throttled if it exceeds CPU limit
  limits:
    memory: "256Mi"
cpu: "500m" # 500 millicores = 0.5 CPU cores# Check actual resource usage vs. requests/limits
kubectl top pods -n default
# Example output:
# NAME CPU(cores) MEMORY(bytes)
# api-server-7d5f8b6c4-abc12 45m 98Mi
# api-server-7d5f8b6c4-def34 52m 102Mi
# api-server-7d5f8b6c4-ghi56 38m 95MiSetting requests too high wastes cluster resources. Setting them too low causes scheduling failures when nodes appear full. Start with requests based on observed usage (from kubectl top) and limits at 2x the request.
Health Checks That Actually Work
Readiness and liveness probes are the most commonly misconfigured settings. Bad probe configuration causes cascading failures.
# ❌ Common mistake: same endpoint, same timing for both probes
readinessProbe:
  httpGet:
    path: /health
    port: 3000
  initialDelaySeconds: 5
  periodSeconds: 5
livenessProbe:
  httpGet:
    path: /health
    port: 3000
  initialDelaySeconds: 5
periodSeconds: 5# ✅ Different timing, different thresholds
readinessProbe:
httpGet:
path: /health/ready
port: 3000
initialDelaySeconds: 5
periodSeconds: 10
failureThreshold: 3
# Pod removed from Service after 3 consecutive failures (30s)
livenessProbe:
httpGet:
path: /health/live
port: 3000
initialDelaySeconds: 30
periodSeconds: 20
failureThreshold: 5
# Pod restarted after 5 consecutive failures (100s)
startupProbe:
httpGet:
path: /health/live
port: 3000
failureThreshold: 30
periodSeconds: 10
# Allows up to 300s for slow-starting appsThe liveness probe should have a longer initialDelaySeconds and higher failureThreshold than the readiness probe. A too-aggressive liveness probe restarts Pods that are temporarily overloaded, creating a restart loop that makes an outage worse.
The readiness /health/ready endpoint should check downstream dependencies (database connection, cache reachability). The liveness /health/live endpoint should be a simple "process is alive" check — never include dependency checks in liveness probes.
ConfigMaps and Secrets
Configuration and secrets should live outside the container image, managed as Kubernetes resources.
# ConfigMap for non-sensitive configuration
apiVersion: v1
kind: ConfigMap
metadata:
  name: api-config
data:
  LOG_LEVEL: "info"
  CACHE_TTL: "300"
  FEATURE_NEW_UI: "true"
---
# Secret for sensitive values (base64 encoded)
apiVersion: v1
kind: Secret
metadata:
  name: db-credentials
type: Opaque
data:
  url: cG9zdGdyZXM6Ly91c2VyOnBhc3NAZGIuZXhhbXBsZS5jb206NTQzMi9teWRi
password: c3VwZXJzZWNyZXQ=# Reference in Deployment
spec:
containers:
- name: api
image: myregistry/api-server:1.4.2
envFrom:
- configMapRef:
name: api-config
env:
- name: DATABASE_URL
valueFrom:
secretKeyRef:
name: db-credentials
key: urlConfigMaps allow updating configuration without rebuilding container images. Changing a ConfigMap and restarting Pods deploys a configuration change in seconds.
Key Takeaways
- Never run bare Pods — always use Deployments for automatic restart and rollout management
- Set resource requests based on observed usage —
kubectl topgives real numbers, not guesses - Separate readiness and liveness probes — different endpoints, different thresholds, different purposes
- Use rolling updates with maxUnavailable: 0 — maintain full capacity during deploys
- Start with ClusterIP services — only expose externally what needs external access
- Keep secrets in Secrets, config in ConfigMaps — never bake environment-specific values into images