Async Concurrency in Node.js: Semaphores and Backpressure
Unbounded Promise.all is a silent OOM killer — here's how to build semaphores, throttled queues, and stream backpressure into your Node.js applications.

Promise.all(items.map(fn)) is one of the most dangerous lines in a Node.js codebase. It looks reasonable — process everything in parallel, await the result. What it actually does is fire every promise simultaneously with zero regard for memory, downstream API rate limits, or database connection pools. At 50 items it's fine. At 50,000 it's an incident.
Controlling concurrency is a first-class concern in production Node.js services, not an afterthought. The patterns are simple to implement and the payoff is enormous.
The Problem with Unbounded Parallelism
Most codebases start with Promise.all because it works during development. Production exposes the flaw.
// ❌ Fires all 10,000 requests simultaneously
async function syncAllUsers(userIds: string[]): Promise<void> {
  await Promise.all(userIds.map((id) => fetchAndSync(id)));
}

// ✅ Processes 20 at a time — predictable memory, no rate-limit bans
async function syncAllUsers(userIds: string[]): Promise<void> {
  await runWithConcurrency(userIds, fetchAndSync, { limit: 20 });
}
The fix isn't complicated, but it requires a concurrency primitive. Let's build one.
Building a Semaphore
A semaphore is a counter with a maximum. When the counter is full, new tasks wait until a slot opens. This is the foundation everything else builds on.
export class Semaphore {
  private queue: Array<() => void> = [];
  private active = 0;

  constructor(private readonly limit: number) {}

  async acquire(): Promise<void> {
    if (this.active < this.limit) {
      this.active++;
      return;
    }

    await new Promise<void>((resolve) => {
      this.queue.push(resolve);
    });
    this.active++;
  }

  release(): void {
    this.active--;
    const next = this.queue.shift();
    if (next) next();
  }

  async run<T>(fn: () => Promise<T>): Promise<T> {
    await this.acquire();
    try {
      return await fn();
    } finally {
      this.release();
    }
  }
}
The semaphore is reusable across the lifetime of a service. Declare it once at the module level and share it across all callers that share the same resource — a database pool, an external API, a file system mount.
// Shared across the entire service — caps total in-flight Stripe calls
const stripeSemaphore = new Semaphore(5);

async function chargeCustomer(customerId: string, amount: number) {
  return stripeSemaphore.run(() =>
    stripe.charges.create({ amount, customer: customerId, currency: "usd" })
  );
}
Throttled Batch Processing
The semaphore handles instantaneous concurrency, but for large arrays you also want to avoid queueing thousands of promises at once. A runWithConcurrency helper processes items in controlled waves.
async function runWithConcurrency<T, R>(
  items: T[],
  fn: (item: T) => Promise<R>,
  options: { limit: number }
): Promise<R[]> {
  const semaphore = new Semaphore(options.limit);
  return Promise.all(items.map((item) => semaphore.run(() => fn(item))));
}
This still creates one promise per item — for extremely large arrays (millions of records), that heap pressure alone can be an issue. In those cases, reach for a chunked iterator instead.
async function* chunks<T>(items: T[], size: number): AsyncGenerator<T[]> {
  for (let i = 0; i < items.length; i += size) {
    yield items.slice(i, i + size);
  }
}

async function processInBatches<T>(
  items: T[],
  fn: (item: T) => Promise<void>,
  batchSize = 100
): Promise<void> {
  for await (const batch of chunks(items, batchSize)) {
    await Promise.all(batch.map(fn));
    // Optional: yield to the event loop between batches
    await new Promise((r) => setImmediate(r));
  }
}
The setImmediate yield lets I/O callbacks (health checks, incoming requests) run between batches. Without it, a long processing loop blocks the event loop even though each individual task is async.
Prefer setImmediate over setTimeout(r, 0) between batches. setImmediate fires after I/O callbacks in the current event loop iteration, while setTimeout with delay 0 actually has ~1ms jitter in Node.js.
Backpressure with Node.js Streams
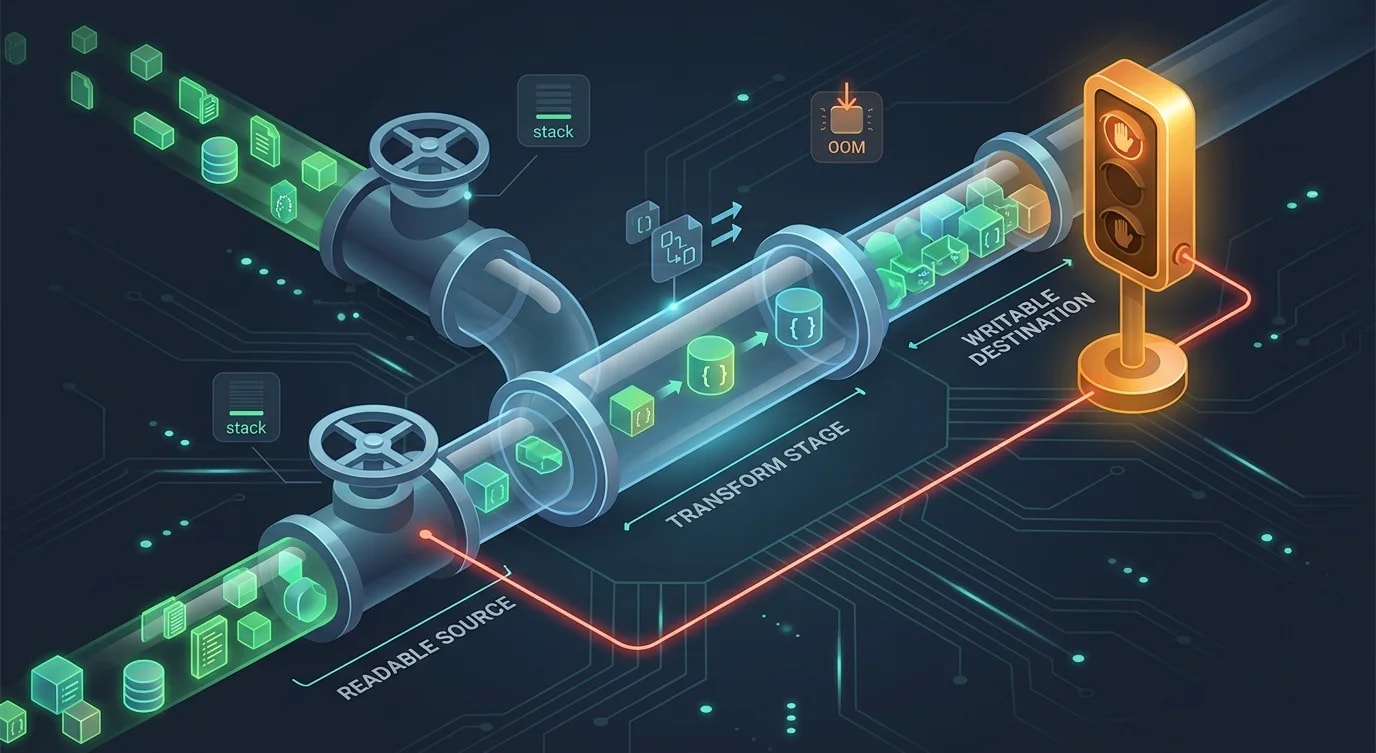
When data volumes are too large to hold in memory at all — think ETL jobs, CSV exports, log processing — streams with built-in backpressure are the right tool. The key is respecting the highWaterMark and not overriding it with unbounded async operations.
import { Transform, TransformCallback } from "node:stream";

class ConcurrentTransform extends Transform {
  private semaphore: Semaphore;
  private pending = 0;
  private drainCallback: (() => void) | null = null;

  constructor(
    private readonly fn: (chunk: unknown) => Promise<unknown>,
    concurrency: number
  ) {
    super({ objectMode: true, highWaterMark: concurrency * 2 });
    this.semaphore = new Semaphore(concurrency);
  }

  _transform(chunk: unknown, _enc: string, callback: TransformCallback): void {
    this.pending++;
    this.semaphore
      .run(() => this.fn(chunk))
      .then((result) => {
        this.push(result);
        this.pending--;
        if (this.pending === 0 && this.drainCallback) {
          this.drainCallback();
          this.drainCallback = null;
        }
      })
      .catch((err) => this.destroy(err));

    // Signal readiness for the next chunk immediately
    // so the readable side doesn't stall waiting for us
    callback();
  }

  _flush(callback: TransformCallback): void {
    if (this.pending === 0) return callback();
    this.drainCallback = callback;
  }
}
The critical insight: call callback() immediately in _transform to keep the stream flowing, but use the semaphore to cap actual in-flight work. The stream's highWaterMark adds a buffer — set it to concurrency * 2 so the readable side always has work queued.
Choosing the Right Concurrency Limit
There's no universal number. Tune based on what you're protecting.
| Resource | Recommended starting limit | Why |
|---|---|---|
| External HTTP API (no SLA) | 5–10 | Avoid 429s; most free-tier limits are per-second |
| External HTTP API (with SLA) | Match their rate limit | Read the docs — Stripe, Twilio publish exact limits |
| PostgreSQL connection pool | pool.max - 2 | Leave headroom for health checks and admin queries |
| Redis | 50–100 | Redis is fast; bottleneck is usually network, not the DB |
| CPU-bound work (worker thread) | os.cpus().length - 1 | One per core minus one for the main thread |
| File system writes | 10–20 | Depends on disk — SSD handles more, spinning disk far less |
Start conservative, load-test under realistic conditions, then raise the limit. It's much easier to increase a semaphore limit than to recover from a cascading database failure.
Preventing Queue Buildup Under Sustained Load
A semaphore queue is unbounded by default. Under sustained load, the queue grows without limit — you've just moved the memory problem from heap to the semaphore. Add a circuit breaker or shed load when the queue exceeds a threshold.
export class BoundedSemaphore extends Semaphore {
  constructor(
    limit: number,
    private readonly maxQueue: number
  ) {
    super(limit);
  }

  async acquire(): Promise<void> {
    // queue is private in parent — expose via a getter in real code
    if (this.queue.length >= this.maxQueue) {
      throw new Error("Semaphore queue full — shedding load");
    }
    return super.acquire();
  }
}
In an HTTP server context, catch this error at the route handler and return 503 Service Unavailable. This is load shedding — a deliberate degradation that protects the service from total collapse.
export async function POST(req: Request) {
  try {
    const result = await processingQueue.run(() => handleRequest(req));
    return Response.json(result);
  } catch (err) {
    if (err instanceof Error && err.message.includes("queue full")) {
      return new Response("Service overloaded", { status: 503 });
    }
    throw err;
  }
}
Key Takeaways
Promise.allon large arrays is unsafe — it creates unbounded parallelism and will OOM or trigger rate limits in production.- A semaphore is the right primitive — it's 30 lines of code, has no dependencies, and composes cleanly with async/await.
- Share semaphores at the resource boundary — one semaphore per database pool, per external API, per disk mount. Don't create them per-request.
- For very large datasets, combine batching with a semaphore — chunked iterators prevent heap pressure from pending promises; the semaphore caps in-flight work.
- Node.js streams need explicit backpressure — call
_transform'scallback()immediately but gate actual work behind a semaphore; tunehighWaterMarkto buffer without flooding. - Add a queue bound and shed load — an unbounded queue is a deferred OOM. Reject early with
503when the queue is full.