Worker Threads in Node.js: Offloading CPU-Bound Work
Learn how to use Node.js worker threads to handle CPU-intensive tasks without blocking the event loop, with thread pooling and type-safe messaging patterns.
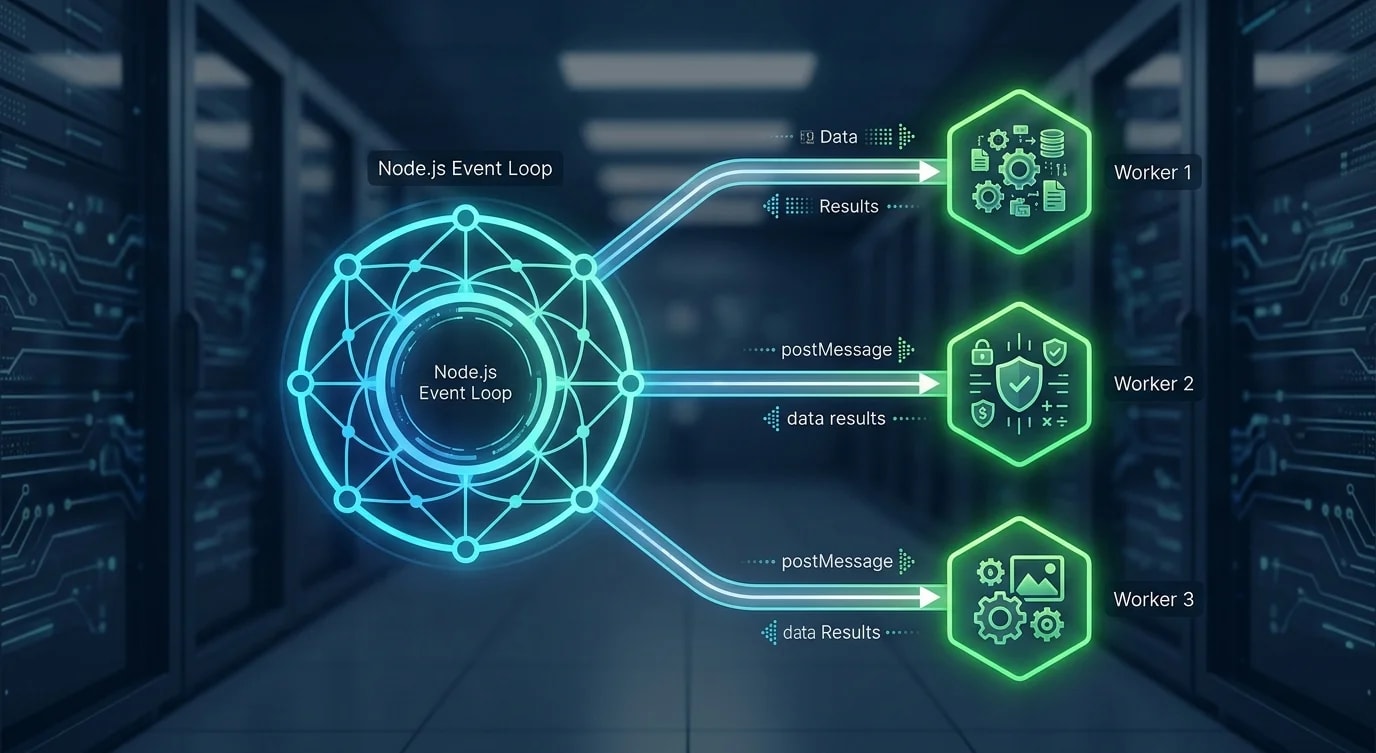
Node.js has a single-threaded event loop, which is great for I/O-bound work and terrible for CPU-bound work. The moment you start doing image processing, cryptographic hashing, or PDF generation inside a request handler, every other request waits. Worker threads fix this — and they're more accessible than most people realize.
The Problem: Blocking the Event Loop
The event loop can only do one thing at a time. A 200ms CPU-bound operation doesn't just slow down one request — it delays every request queued behind it. At low traffic, this is invisible. Under load, it's catastrophic.
// ❌ Runs on the main thread — blocks everything while computing
export async function POST(req: Request) {
  const { data } = await req.json();
  const result = heavyComputation(data); // 500ms of pure CPU work
  return Response.json({ result });
}

// ✅ Offloads to a worker thread — main thread stays responsive
export async function POST(req: Request) {
  const { data } = await req.json();
  const result = await pool.run({ type: "COMPUTE", payload: data });
  return Response.json({ result });
}
The fix isn't to use setImmediate or break work into microtask chunks (though that has its place). For genuinely CPU-intensive work, the answer is worker threads.
Setting Up a Basic Worker
Node.js exposes workers through the worker_threads module. A worker runs in its own V8 instance with its own event loop. Communication happens through message passing — no shared memory by default.
// workers/compute.worker.ts
import { parentPort, workerData } from "worker_threads";

if (!parentPort) throw new Error("Must be run as a worker");

function heavyComputation(input: number[]): number {
  // Simulate expensive work — sorting, hashing, parsing large datasets, etc.
  return input.reduce((acc, val) => acc + Math.sqrt(val * Math.PI), 0);
}

const result = heavyComputation(workerData.input);
parentPort.postMessage({ result });// lib/run-in-worker.ts
import { Worker } from "worker_threads";
import path from "path";
export function runComputeWorker(input: number[]): Promise<number> {
return new Promise((resolve, reject) => {
const worker = new Worker(
path.resolve(__dirname, "../workers/compute.worker.js"),
{ workerData: { input } }
);
worker.on("message", ({ result }) => resolve(result));
worker.on("error", reject);
worker.on("exit", (code) => {
if (code !== 0) reject(new Error(`Worker exited with code ${code}`));
});
});
}Spawning a worker per request works for prototyping, but carries real overhead — thread startup alone costs 50–100ms. The right production pattern is a pool.
Building a Thread Pool
Creating and destroying threads for every task wastes the startup cost and creates latency spikes. A pool keeps threads alive and reuses them across requests.
// lib/worker-pool.ts
import { Worker } from "worker_threads";
import path from "path";

interface PoolTask<T> {
  data: unknown;
  resolve: (value: T) => void;
  reject: (error: Error) => void;
}

export class WorkerPool<T = unknown> {
  private idle: Worker[] = [];
  private queue: PoolTask<T>[] = [];
  private currentTask = new Map<Worker, PoolTask<T>>();

  constructor(workerPath: string, size: number) {
    for (let i = 0; i < size; i++) {
      const worker = new Worker(path.resolve(workerPath));
      this.idle.push(worker);

      worker.on("message", (result: T) => {
        const task = this.currentTask.get(worker);
        if (task) {
          this.currentTask.delete(worker);
          task.resolve(result);
        }
        this.idle.push(worker);
        this.drain();
      });

      worker.on("error", (err) => {
        const task = this.currentTask.get(worker);
        if (task) task.reject(err);
        this.idle.push(worker);
        this.drain();
      });
    }
  }

  run(data: unknown): Promise<T> {
    return new Promise((resolve, reject) => {
      this.queue.push({ data, resolve, reject });
      this.drain();
    });
  }

  private drain() {
    if (this.queue.length === 0 || this.idle.length === 0) return;
    const worker = this.idle.pop()!;
    const task = this.queue.shift()!;
    this.currentTask.set(worker, task);
    worker.postMessage(task.data);
  }
}
Pool size should match your CPU core count minus one — leave a core for the main thread and I/O handling. os.cpus().length - 1 is a reliable default for most server workloads.
Type-Safe Message Contracts
Workers communicate through postMessage, which is inherently any. A typed message contract catches mismatches at compile time rather than at runtime in production.
// types/worker-messages.ts
export type WorkerRequest =
  | { type: "HASH"; payload: { data: string; algorithm: "sha256" | "sha512" } }
  | { type: "COMPRESS"; payload: { buffer: ArrayBuffer; level: number } }
  | { type: "PARSE_CSV"; payload: { csv: string; delimiter: string } };

export type WorkerResponse =
  | { type: "HASH"; result: string }
  | { type: "COMPRESS"; result: ArrayBuffer }
  | { type: "PARSE_CSV"; result: Record<string, string>[] };

// workers/multipurpose.worker.ts
import { parentPort } from "worker_threads";
import type { WorkerRequest, WorkerResponse } from "../types/worker-messages";

parentPort?.on("message", (req: WorkerRequest) => {
  let response: WorkerResponse;

  switch (req.type) {
    case "HASH":
      response = { type: "HASH", result: hashData(req.payload) };
      break;
    case "COMPRESS":
      response = { type: "COMPRESS", result: compress(req.payload) };
      break;
    case "PARSE_CSV":
      response = { type: "PARSE_CSV", result: parseCsv(req.payload) };
      break;
  }

  parentPort?.postMessage(response);
});
TypeScript's exhaustive switch will error at compile time if you add a new message type without handling it in the worker. That's exactly the safety you want across async thread boundaries.
Pass ArrayBuffer values as Transferable objects using the second argument of postMessage(data, [buffer]). This transfers ownership instead of cloning — zero copy cost regardless of payload size.
When Not to Use Worker Threads
Worker threads aren't free. Structured cloning on postMessage is O(n) in payload size. For large buffers, use SharedArrayBuffer or transferable ownership. For small payloads, the overhead may exceed the benefit entirely.
| Use case | Worker threads? | Reason |
|---|---|---|
| Image / video processing | Yes | CPU-heavy, buffers are transferable |
| Cryptographic hashing | Yes | CPU-bound, small payloads |
| ML inference (ONNX, WASM) | Yes | Long-running, CPU or WASM heavy |
| Database queries | No | I/O-bound, async drivers handle this |
| External API calls | No | I/O-bound, no CPU work involved |
| JSON parsing (< 1 MB) | No | Overhead outweighs benefit |
| JSON parsing (> 10 MB) | Yes | CPU cost dominates at scale |
The practical threshold: if perf_hooks shows your handler spending more than 10ms in synchronous CPU work, it's a worker thread candidate.
Putting It Together in a Real Route
// app/api/image/route.ts
import { WorkerPool } from "@/lib/worker-pool";
import type { WorkerResponse } from "@/types/worker-messages";
import os from "os";

// Initialize once at module load — not per request
const pool = new WorkerPool<WorkerResponse>(
  require.resolve("@/workers/image-processor.worker"),
  Math.max(1, os.cpus().length - 1)
);

export async function POST(req: Request) {
  const formData = await req.formData();
  const file = formData.get("image") as File | null;

  if (!file) {
    return Response.json({ error: "No file provided" }, { status: 400 });
  }

  const buffer = await file.arrayBuffer();

  try {
    const response = await pool.run({
      type: "COMPRESS",
      payload: { buffer, level: 8 },
    }) as Extract<WorkerResponse, { type: "COMPRESS" }>;

    return new Response(response.result, {
      headers: { "Content-Type": "image/webp" },
    });
  } catch (err) {
    console.error("[image-worker] processing failed:", err);
    return Response.json({ error: "Processing failed" }, { status: 500 });
  }
}
The pool is created once at module initialization and reused across every request. Workers stay warm. The event loop stays free. Overflow requests queue automatically and drain as threads become available.
Key Takeaways
- CPU-bound work blocks every request — a single 200ms synchronous operation creates tail latency spikes across all concurrent requests under load
- Spawn a pool, not individual workers — per-request worker creation defeats the purpose; reuse threads and pay startup cost once
- Transfer large buffers, don't clone them — pass
ArrayBufferas aTransferableto avoid the serialization cost on every message - Type your message contracts —
postMessageisanyby default; discriminated unions give compile-time safety across thread boundaries - Size the pool to your cores —
os.cpus().length - 1is the right default; leave room for the event loop and I/O - Profile before optimizing — worker threads add real complexity; only reach for them when you can measure the event loop blockage with
perf_hooksor clinic.js